

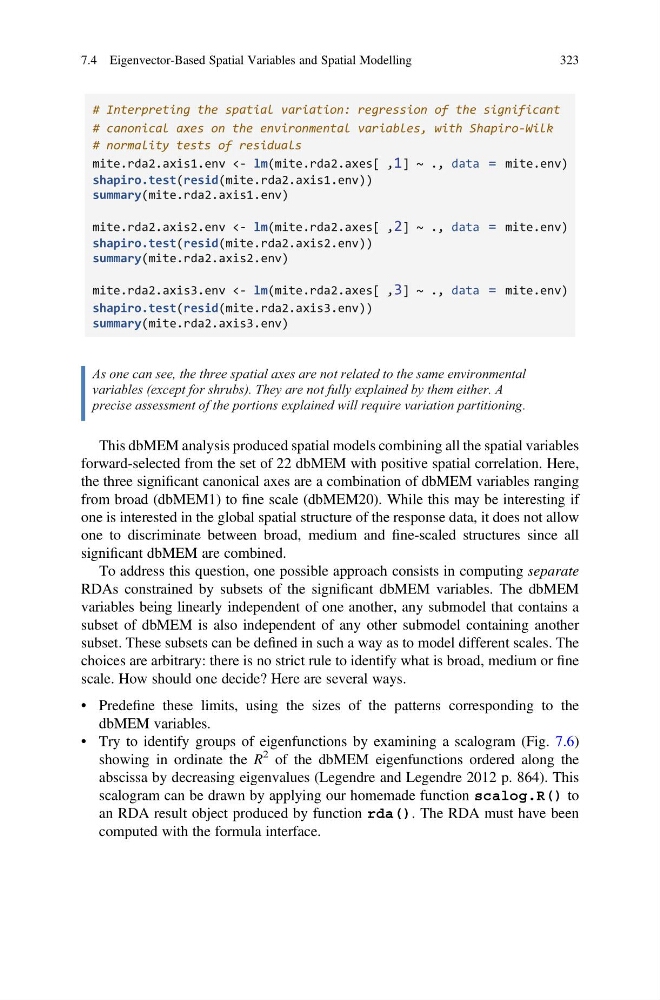
# Interpreting the spatial variation: regression of the significant
# canonical axes on the environmental variables, with Shapiro-Wilk
# normality tests of residuals
mite.rda2.axis1.env <- lm(mite.rda2.axes[ ,1] ~ ., data = mite.env)
shapiro.test(resid(mite.rda2.axis1.env))
summary(mite.rda2.axis1.env)
mite.rda2.axis2.env <- lm(mite.rda2.axes[ ,2] ~ ., data = mite.env)
shapiro.test(resid(mite.rda2.axis2.env))
summary(mite.rda2.axis2.env)
mite.rda2.axis3.env <- lm(mite.rda2.axes[ ,3] ~ ., data = mite.env)
shapiro.test(resid(mite.rda2.axis3.env))
summary(mite.rda2.axis3.env)
As one can see, the three spatial axes are not related to the same environmental
variables (except for shrubs). They are not fully explained by them either. A
precise assessment of the portions explained will require variation partitioning.
This dbMEM analysis produced spatial models combining all the spatial variables
forward-selected from the set of 22 dbMEM with positive spatial correlation. Here,
the three significant canonical axes are a combination of dbMEM variables ranging
from broad (dbMEM1) to fine scale (dbMEM20). While this may be interesting if
one is interested in the global spatial structure of the response data, it does not allow
one to discriminate between broad, medium and fine-scaled structures since all
significant dbMEM are combined.
To address this question, one possible approach consists in computing separate
RDAs constrained by subsets of the significant dbMEM variables. The dbMEM
variables being linearly independent of one another, any submodel that contains a
subset of dbMEM is also independent of any other submodel containing another
subset. These subsets can be defined in such a way as to model different scales. The
choices are arbitrary: there is no strict rule to identify what is broad, medium or fine
scale. How should one decide? Here are several ways.
• Predefine these limits, using the sizes of the patterns corresponding to the
dbMEM variables.
• Try to identify groups of eigenfunctions by examining a scalogram (Fig. 7.6)
showing in ordinate the R
2 of the dbMEM eigenfunctions ordered along the
abscissa by decreasing eigenvalues (Legendre and Legendre 2012 p. 864). This
scalogram can be drawn by applying our homemade function scalog.R() to
an RDA result object produced by function rda(). The RDA must have been
computed with the formula interface.
7.4 Eigenvector-Based Spatial Variables and Spatial Modelling
323