

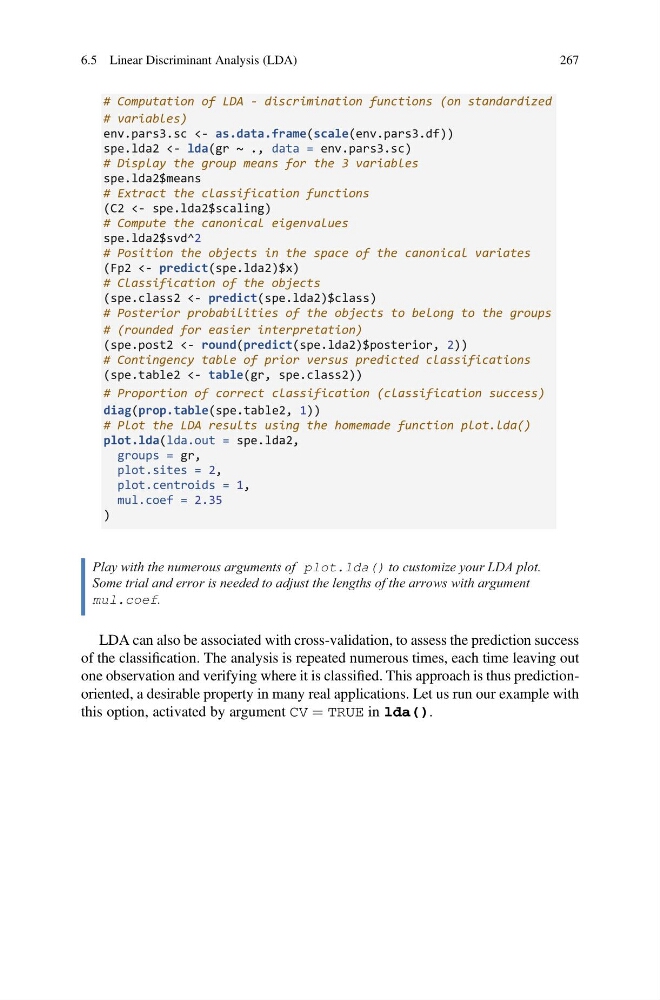
# Computation of LDA - discrimination functions (on standardized
# variables)
env.pars3.sc <- as.data.frame(scale(env.pars3.df))
spe.lda2 <- lda(gr ~ ., data = env.pars3.sc)
# Display the group means for the 3 variables
spe.lda2$means
# Extract the classification functions
(C2 <- spe.lda2$scaling)
# Compute the canonical eigenvalues
spe.lda2$svd^2
# Position the objects in the space of the canonical variates
(Fp2 <- predict(spe.lda2)$x)
# Classification of the objects
(spe.class2 <- predict(spe.lda2)$class)
# Posterior probabilities of the objects to belong to the groups
# (rounded for easier interpretation)
(spe.post2 <- round(predict(spe.lda2)$posterior, 2))
# Contingency table of prior versus predicted classifications
(spe.table2 <- table(gr, spe.class2))
# Proportion of correct classification (classification success)
diag(prop.table(spe.table2, 1))
# Plot the LDA results using the homemade function plot.lda()
plot.lda(lda.out = spe.lda2,
groups = gr,
plot.sites = 2,
plot.centroids = 1,
mul.coef = 2.35
)
Play with the numerous arguments of plot.lda() to customize your LDA plot.
Some trial and error is needed to adjust the lengths of the arrows with argument
mul.coef.
LDA can also be associated with cross-validation, to assess the prediction success
of the classification. The analysis is repeated numerous times, each time leaving out
one observation and verifying where it is classified. This approach is thus predictionoriented, a desirable property in many real applications. Let us run our example with
this option, activated by argument CV ¼ TRUE in lda().
6.5 Linear Discriminant Analysis (LDA)
267