

6.3 Confidence Levels: Stochastic Global Optimization
149
will be highly suspect. When this occurs we will either choose a new parameter to
characterize the flaw, or acquire data at a lower frequency.
These metrics are not available to us in the current inspection method, in which
analog instruments acquire data that are then interpreted by humans using hardware
standards. The opportunity to use these metrics is a significant advantage to the
model-based inversion paradigm that we propose in this paper.
6.3 Confidence Levels: Stochastic Global Optimization
We can extend the previous results to obtain a statistical measure of confidence in
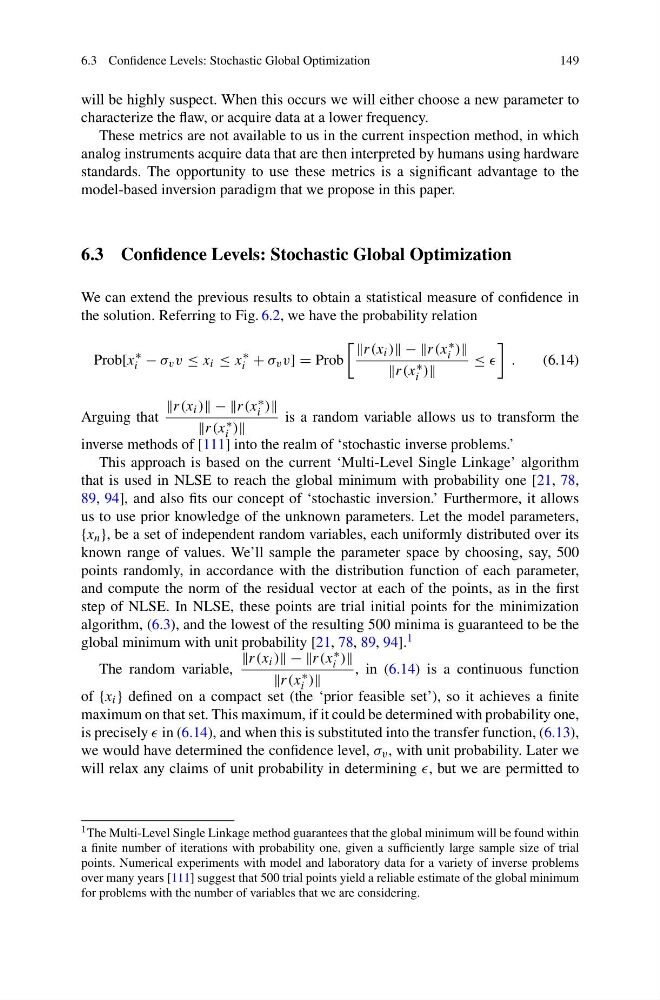
the solution. Referring to Fig. 6.2, we have the probability relation
Prob[x
∗
i − σ v v ≤ x i ≤ x
∗
i + σ v v] = Prob
r(x i ) − −r(x ∗
i )
r(x ∗
i )
≤
.
(6.14)
Arguing that
r(x i ) − −r(x ∗
i )
r(x ∗
i )
is a random variable allows us to transform the
inverse methods of [111] into the realm of ‘stochastic inverse problems.’
This approach is based on the current ‘Multi-Level Single Linkage’ algorithm
that is used in NLSE to reach the global minimum with probability one [21, 78,
89, 94], and also fits our concept of ‘stochastic inversion.’ Furthermore, it allows
us to use prior knowledge of the unknown parameters. Let the model parameters,
{x n }, be a set of independent random variables, each uniformly distributed over its
known range of values. We’ll sample the parameter space by choosing, say, 500
points randomly, in accordance with the distribution function of each parameter,
and compute the norm of the residual vector at each of the points, as in the first
step of NLSE. In NLSE, these points are trial initial points for the minimization
algorithm, (6.3), and the lowest of the resulting 500 minima is guaranteed to be the
global minimum with unit probability [21, 78, 89, 94]. 1
The random variable,
r(x i ) − −r(x ∗
i )
r(x ∗
i )
, in (6.14) is a continuous function
of {x i } defined on a compact set (the ‘prior feasible set’), so it achieves a finite
maximum on that set. This maximum, if it could be determined with probability one,
is precisely in (6.14), and when this is substituted into the transfer function, (6.13),
we would have determined the confidence level, σ v , with unit probability. Later we
will relax any claims of unit probability in determining , but we are permitted to
1 The Multi-Level Single Linkage method guarantees that the global minimum will be found within
a finite number of iterations with probability one, given a sufficiently large sample size of trial
points. Numerical experiments with model and laboratory data for a variety of inverse problems
over many years [111] suggest that 500 trial points yield a reliable estimate of the global minimum
for problems with the number of variables that we are considering.