

46
3 Basics of Neural Networks
(N − 1) extra degrees of freedom are prepared, and considering the corresponding
N Hamiltonians
H
1
J 1 ,x (h 1 ) ,
(3.44)
H
2
J 2 ,h 1
(h 2 ) ,
(3.45)
. . .
(3.46)
H
N
J N ,h N−1
(d) ,
(3.47)
the model is
Q J (d|x) =
h 1 ,h 2 ,...,h N−1
Q J N (d|h N−1 ) . . . Q J 2 (h 2 |h 1 )Q J 1 (h 1 |x) .
(3.48)
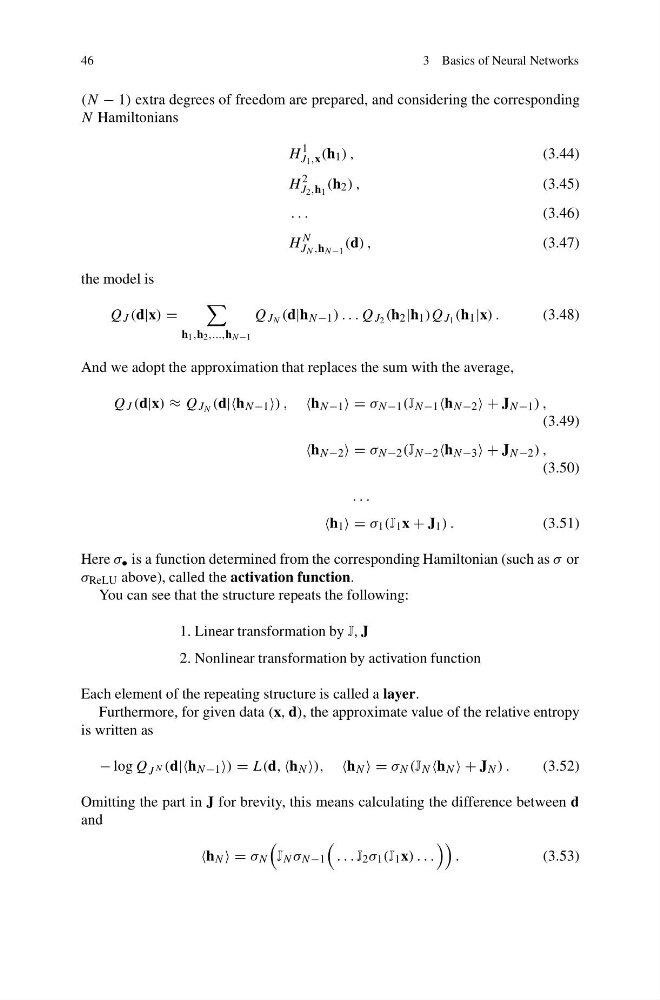
And we adopt the approximation that replaces the sum with the average,
Q J (d|x) ≈ Q J N (d||h N−1 ) , h N−1 = σ N−1 (J N−1 h N−2 + J N−1 ) ,
(3.49)
h N−2 = σ N−2 (J N−2 h N−3 + J N−2 ) ,
(3.50)
. . .
h 1 = σ 1 (J 1 x + J 1 ) .
(3.51)
Here σ • is a function determined from the corresponding Hamiltonian (such as σ or
σ ReLU above), called the activation function.
You can see that the structure repeats the following:
1. Linear transformation by J, J
2. Nonlinear transformation by activation function
Each element of the repeating structure is called a layer.
Furthermore, for given data (x, d), the approximate value of the relative entropy
is written as
− log Q J N (d||h N−1 ) = L(d, h N ), h N = σ N (J N h N + J N ) .
(3.52)
Omitting the part in J for brevity, this means calculating the difference between d
and
h N = σ N
J N σ N−1
. . . J 2 σ 1 (J 1 x) . . .
.
(3.53)