

3.2 Derivation of Backpropagation Method Using Bracket Notation
47
In the usual context of deep learning, the parameters are often written as
J = W,
(3.54)
J = b,
(3.55)
and referred to as weight W and bias b.
The neural network has been “derived.” In the next section, we will look at how
learning can proceed.
3.2 Derivation of Backpropagation Method Using Bracket
Notation
We shall derive the famous backpropagation method of the neural network [31].
The backpropagation method is just a combination of the differential method of
composite functions and a little bit of linear algebra. Here we derive it by using the
quantum mechanics notation representing ket |•• as an element in a vector space
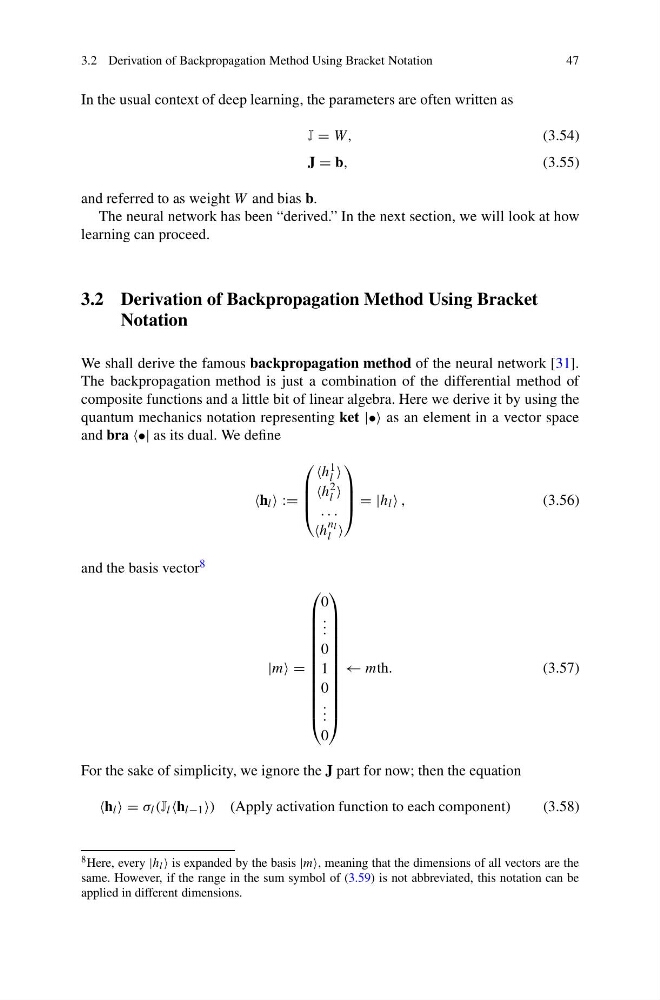
and bra •| as its dual. We define
l :=
⎛
⎜
⎜
⎝
1
l
2
l
. . .
n l
l
⎞
⎟
⎟
⎠ = |h l ,
(3.56)
and the basis vector 8
|m =
⎛
⎜
⎜
⎜
⎜
⎜
⎜
⎜
⎜
⎜
⎜
⎜
⎝
0
. . .
0
1
0
. . .
0
⎞
⎟
⎟
⎟
⎟
⎟
⎟
⎟
⎟
⎟
⎟
⎟
⎠
← mth.
(3.57)
For the sake of simplicity, we ignore the J part for now; then the equation
l = σ l (J l l−1 (Apply activation function to each component)
(3.58)
8 Here, every |h l is expanded by the basis |m, meaning that the dimensions of all vectors are the
same. However, if the range in the sum symbol of (3.59) is not abbreviated, this notation can be
applied in different dimensions.