

3.1 Error Function from Statistical Mechanics
43
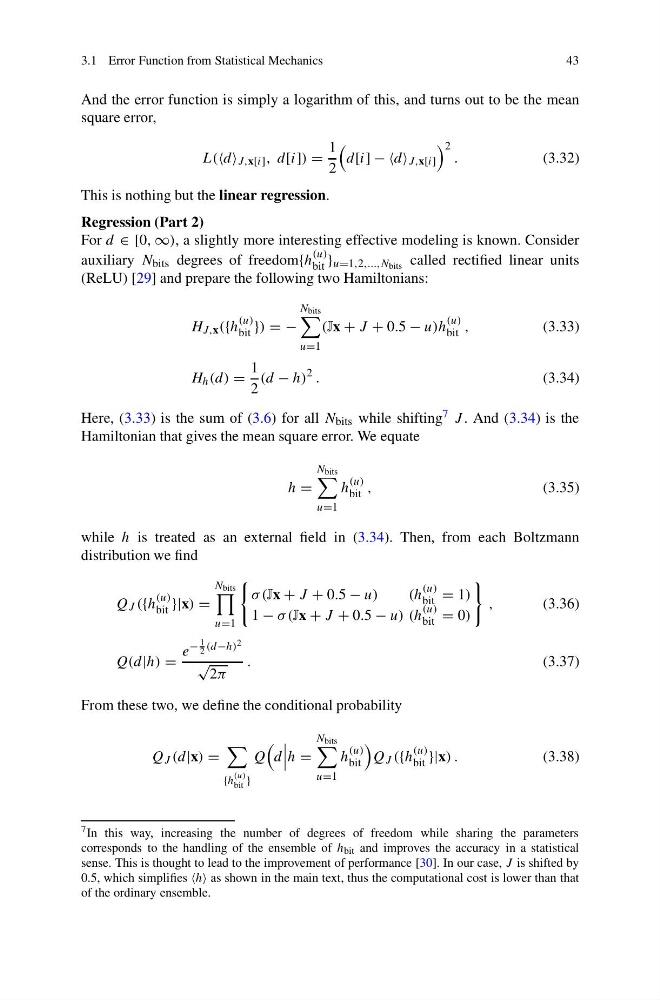
And the error function is simply a logarithm of this, and turns out to be the mean
square error,
L( J,x[i] , d[i]) =
1
2
d[i] − −d J,x[i]
2
.
(3.32)
This is nothing but the linear regression.
Regression (Part 2)
For d ∈ [0, ∞), a slightly more interesting effective modeling is known. Consider
auxiliary N bits degrees of freedom{h
(u)
bit } u=1,2,...,N bits called rectified linear units
(ReLU) [29] and prepare the following two Hamiltonians:
H J,x ({h
(u)
bit }) = −
N bits
u=1
(Jx + J + 0.5 − u)h
(u)
bit ,
(3.33)
H h (d) =
1
2
(d − h)
2 .
(3.34)
Here, (3.33) is the sum of (3.6) for all N bits while shifting 7 J . And (3.34) is the
Hamiltonian that gives the mean square error. We equate
h =
N bits
u=1
h
(u)
bit ,
(3.35)
while h is treated as an external field in (3.34). Then, from each Boltzmann
distribution we find
Q J ({h
(u)
bit }|x) =
N bits
u=1
σ (Jx + J + 0.5 − u)
(h
(u)
bit = 1)
1 − σ (Jx + J + 0.5 − u) (h
(u)
bit = 0)
,
(3.36)
Q(d|h) =
e
−
1
2 (d−h) 2
√
2π
.
(3.37)
From these two, we define the conditional probability
Q J (d|x) =
{h
(u)
bit }
Q
d
h =
N bits
u=1
h
(u)
bit
Q J ({h
(u)
bit }|x) .
(3.38)
7 In this way, increasing the number of degrees of freedom while sharing the parameters
corresponds to the handling of the ensemble of h bit and improves the accuracy in a statistical
sense. This is thought to lead to the improvement of performance [30]. In our case, J is shifted by
0.5, which simplifies as shown in the main text, thus the computational cost is lower than that
of the ordinary ensemble.