

9.1 System Description
161
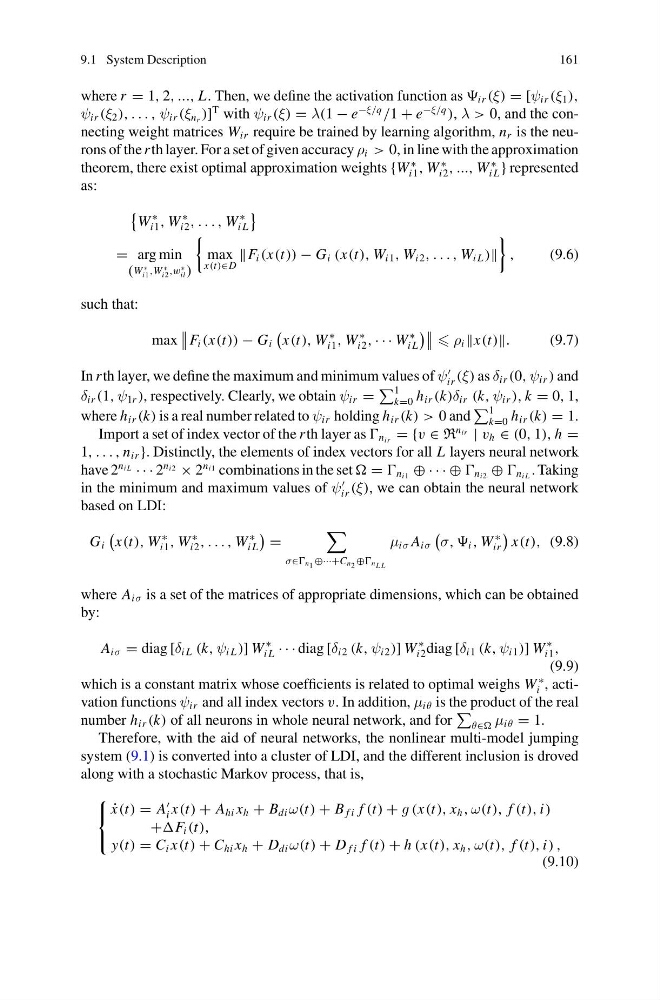
where r = 1, 2, ..., L. Then, we define the activation function as ir (ξ) = [ψ ir (ξ 1 ),
ψ ir (ξ 2 ), . . . , ψ ir (ξ n r )]
T with ψ ir (ξ) = λ(1 − e
−ξ/q
/1 + e
−ξ/q
), λ > 0, and the connecting weight matrices W ir require be trained by learning algorithm, n r is the neurons of the r th layer. For a set of given accuracy ρ i > 0, in line with the approximation
theorem, there exist optimal approximation weights {W
∗
i1 , W
∗
i2 , ..., W
∗
i L } represented
as:
W
∗
i1 , W
∗
i2 , . . . , W
∗
i L
= arg min
(W
∗
i1 ,W
∗
i2 ,w
∗
il )
max
x(t)∈D
F i (x(t)) − G i (x(t), W i1 , W i2 , . . . , W i L )
,
(9.6)
such that:
max
F i (x(t)) − G i
x(t), W
∗
i1 , W
∗
i2 , · · · W
∗
i L
ρ i x(t).
(9.7)
In r th layer, we define the maximum and minimum values of ψ
ir (ξ) as δ ir (0, ψ ir ) and
δ ir (1, ψ 1r ), respectively. Clearly, we obtain ψ ir =
1
k=0 h ir (k)δ ir (k, ψ ir ), k = 0, 1,
where h ir (k) is a real number related to ψ ir holding h ir (k) > 0 and
1
k=0 h ir (k) = 1.
Import a set of index vector of the r th layer as n ir = {v ∈ R
n ir | v h ∈ (0, 1), h =
1, . . . , n ir }. Distinctly, the elements of index vectors for all L layers neural network
have 2
n i L · · · 2
n i2 × 2
n i1 combinations in the set = n i1 ⊕ · · · ⊕ n i2 ⊕ n i L . Taking
in the minimum and maximum values of ψ
ir (ξ), we can obtain the neural network
based on LDI:
G i
x(t), W
∗
i1 , W
∗
i2 , . . . , W
∗
i L
=
σ∈ n 1 ⊕···+C n 2 ⊕ n L L
μ iσ A iσ
σ, , i , W
∗
ir
x(t), (9.8)
where A iσ is a set of the matrices of appropriate dimensions, which can be obtained
by:
A iσ = diag [δ i L (k, ψ i L )] W
∗
i L · · · diag [δ i2 (k, ψ i2 )] W
∗
i2 diag [δ i1 (k, ψ i1 )] W
∗
i1 ,
(9.9)
which is a constant matrix whose coefficients is related to optimal weighs W
∗
i , activation functions ψ ir and all index vectors v. In addition, μ iθ is the product of the real
number h ir (k) of all neurons in whole neural network, and for
θ∈ μ iθ = 1.
Therefore, with the aid of neural networks, the nonlinear multi-model jumping
system (9.1) is converted into a cluster of LDI, and the different inclusion is droved
along with a stochastic Markov process, that is,
⎧
⎨
⎩
˙
x(t) = A
i x(t) + A hi x h + B di ω(t) + B f i f (t) + g (x(t), x h , ω(t), f (t), i)
+F i (t),
y(t) = C i x(t) + C hi x h + D di ω(t) + D f i f (t) + h (x(t), x h , ω(t), f (t), i) ,
(9.10)