

124
F. Rathke et al.
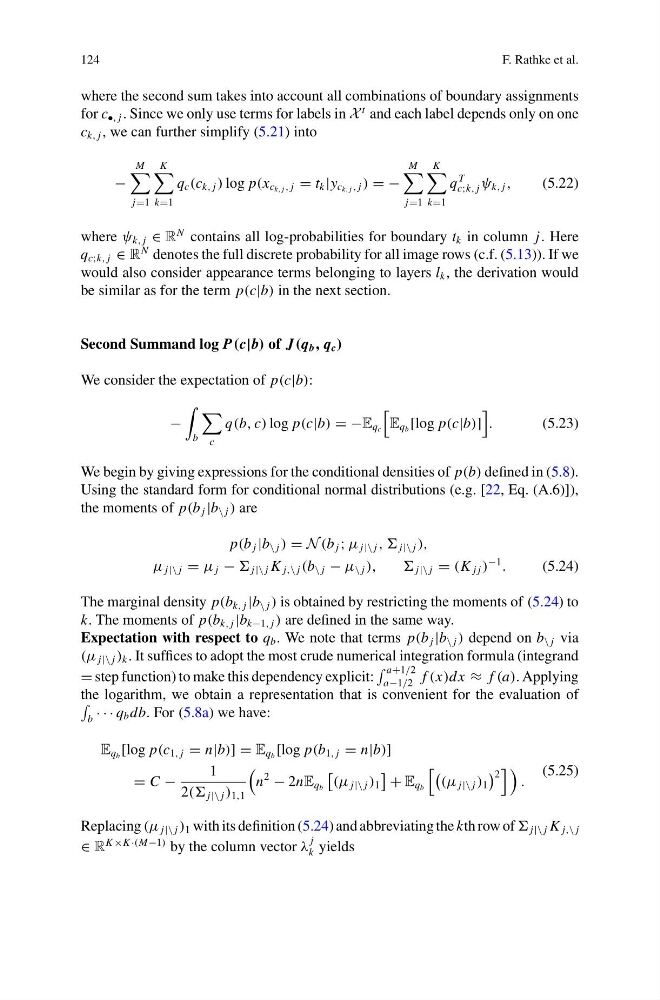
where the second sum takes into account all combinations of boundary assignments
for c •, j . Since we only use terms for labels in X
t and each label depends only on one
c k, j , we can further simplify (5.21) into
−
M
j=1
K
k=1
q c (c k, j ) log p(x c k, j , j = t k |y c k, j , j ) = −
M
j=1
K
k=1
q
T
c;k, j ψ k, j ,
(5.22)
where ψ k, j ∈ R
N contains all log-probabilities for boundary t k in column j. Here
q c;k, j ∈ R
N denotes the full discrete probability for all image rows (c.f. (5.13)). If we
would also consider appearance terms belonging to layers l k , the derivation would
be similar as for the term p(c|b) in the next section.
Second Summand log P(c|b) of J(q b , q c )
We consider the expectation of p(c|b):
−
b
c
q(b, c) log p(c|b) = −E q c
E q b [log p(c|b)]
.
(5.23)
We begin by giving expressions for the conditional densities of p(b) defined in (5.8).
Using the standard form for conditional normal distributions (e.g. [22, Eq. (A.6)]),
the moments of p(b j |b \ j ) are
p(b j |b \ j ) = N (b j ; μ j|\ j , , j|\ j ),
μ j|\ j = μ j − j|\ j K j,\ j (b \ j − μ \ j ),
, j|\ j = (K j j )
−1
.
(5.24)
The marginal density p(b k, j |b \ j ) is obtained by restricting the moments of (5.24) to
k. The moments of p(b k, j |b k−1, j ) are defined in the same way.
Expectation with respect to q b . We note that terms p(b j |b \ j ) depend on b \ j via
(μ j|\ j ) k . It suffices to adopt the most crude numerical integration formula (integrand
= step function) to make this dependency explicit:
a+1/2
a−1/2 f (x)dx ≈ f (a). Applying
the logarithm, we obtain a representation that is convenient for the evaluation of
b · · · q b db. For (5.8a) we have:
E q b [log p(c 1, j = n|b)] = E q b [log p(b 1, j = n|b)]
= C −
1
2(( j|\ j ) 1,1
n
2
− 2nE q b
(μ j|\ j ) 1
+ E q b
(μ j|\ j ) 1
2
.
(5.25)
Replacing (μ j|\ j ) 1 with its definition (5.24) and abbreviating the kth row of j|\ j K j,\ j
∈ R
K ×K ·(M−1) by the column vector λ
j
k yields