

162
6 Experimental Validation of the Methodology
as the values of the idle state. On the other hand, the data sets of the idle state
with rather high values are assigned to the cluster of the productive state. The
use of a clustering algorithm requires a complex post-processing of the clustered
data, to resolve blurring caused by overlapping values between machine states.
Since the elaborate post-processing of the cluster data thus makes the argument
of the time savings obsolete, the machine state simulation in the real production
is the method of choice for the verification of the state-based energy consumption
profiles in this work.
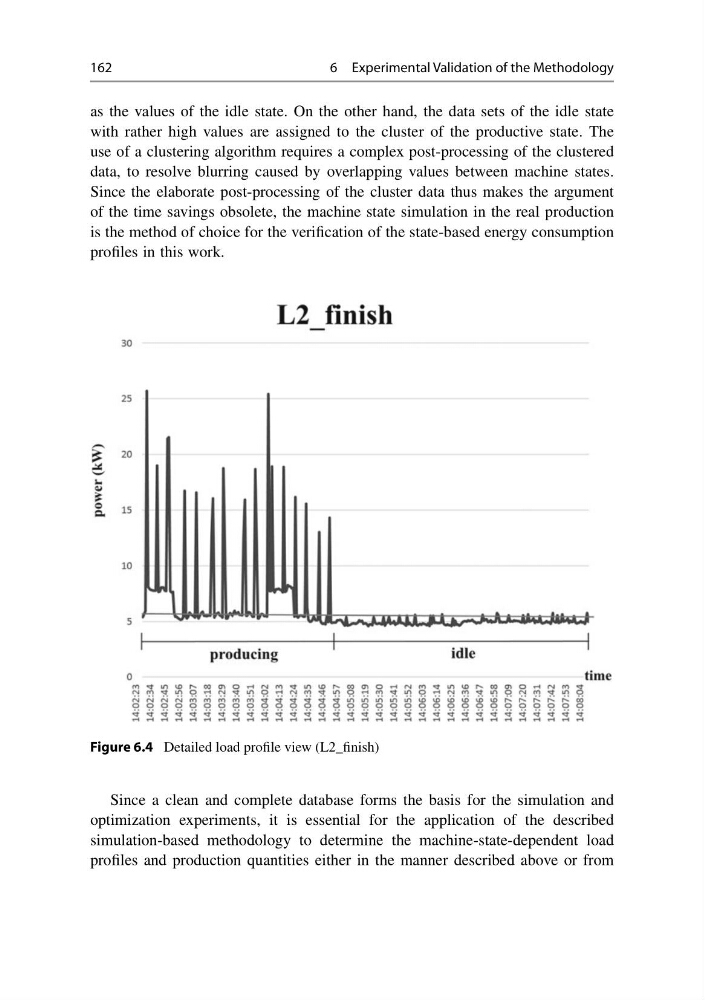
Figure 6.4 Detailed load profile view (L2_finish)
Since a clean and complete database forms the basis for the simulation and
optimization experiments, it is essential for the application of the described
simulation-based methodology to determine the machine-state-dependent load
profiles and production quantities either in the manner described above or from