

8 Chain Rule Optimal Transport
205
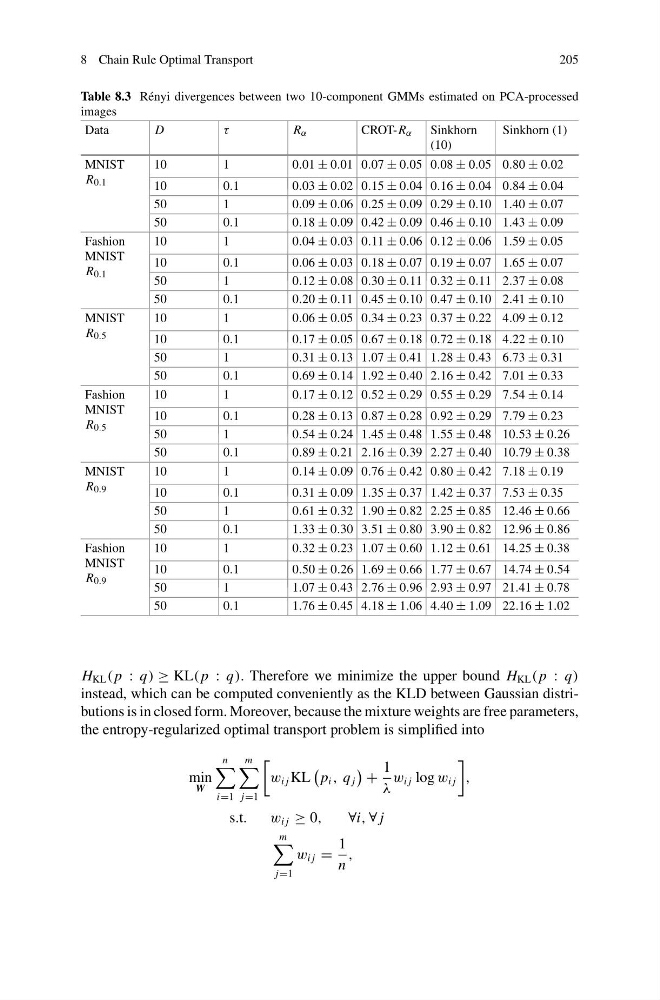
Table 8.3 Rényi divergences between two 10-component GMMs estimated on PCA-processed
images
Data
D
τ
R α
CROT-R α Sinkhorn
(10)
Sinkhorn (1)
MNIST
R 0.1
10
1
0.01 ± 0.01 0.07 ± 0.05 0.08 ± 0.05 0.80 ± 0.02
10
0.1
0.03 ± 0.02 0.15 ± 0.04 0.16 ± 0.04 0.84 ± 0.04
50
1
0.09 ± 0.06 0.25 ± 0.09 0.29 ± 0.10 1.40 ± 0.07
50
0.1
0.18 ± 0.09 0.42 ± 0.09 0.46 ± 0.10 1.43 ± 0.09
Fashion
MNIST
R 0.1
10
1
0.04 ± 0.03 0.11 ± 0.06 0.12 ± 0.06 1.59 ± 0.05
10
0.1
0.06 ± 0.03 0.18 ± 0.07 0.19 ± 0.07 1.65 ± 0.07
50
1
0.12 ± 0.08 0.30 ± 0.11 0.32 ± 0.11 2.37 ± 0.08
50
0.1
0.20 ± 0.11 0.45 ± 0.10 0.47 ± 0.10 2.41 ± 0.10
MNIST
R 0.5
10
1
0.06 ± 0.05 0.34 ± 0.23 0.37 ± 0.22 4.09 ± 0.12
10
0.1
0.17 ± 0.05 0.67 ± 0.18 0.72 ± 0.18 4.22 ± 0.10
50
1
0.31 ± 0.13 1.07 ± 0.41 1.28 ± 0.43 6.73 ± 0.31
50
0.1
0.69 ± 0.14 1.92 ± 0.40 2.16 ± 0.42 7.01 ± 0.33
Fashion
MNIST
R 0.5
10
1
0.17 ± 0.12 0.52 ± 0.29 0.55 ± 0.29 7.54 ± 0.14
10
0.1
0.28 ± 0.13 0.87 ± 0.28 0.92 ± 0.29 7.79 ± 0.23
50
1
0.54 ± 0.24 1.45 ± 0.48 1.55 ± 0.48 10.53 ± 0.26
50
0.1
0.89 ± 0.21 2.16 ± 0.39 2.27 ± 0.40 10.79 ± 0.38
MNIST
R 0.9
10
1
0.14 ± 0.09 0.76 ± 0.42 0.80 ± 0.42 7.18 ± 0.19
10
0.1
0.31 ± 0.09 1.35 ± 0.37 1.42 ± 0.37 7.53 ± 0.35
50
1
0.61 ± 0.32 1.90 ± 0.82 2.25 ± 0.85 12.46 ± 0.66
50
0.1
1.33 ± 0.30 3.51 ± 0.80 3.90 ± 0.82 12.96 ± 0.86
Fashion
MNIST
R 0.9
10
1
0.32 ± 0.23 1.07 ± 0.60 1.12 ± 0.61 14.25 ± 0.38
10
0.1
0.50 ± 0.26 1.69 ± 0.66 1.77 ± 0.67 14.74 ± 0.54
50
1
1.07 ± 0.43 2.76 ± 0.96 2.93 ± 0.97 21.41 ± 0.78
50
0.1
1.76 ± 0.45 4.18 ± 1.06 4.40 ± 1.09 22.16 ± 1.02
H KL ( p : q) ≥ KL( p : q). Therefore we minimize the upper bound H KL ( p : q)
instead, which can be computed conveniently as the KLD between Gaussian distributions is in closed form. Moreover, because the mixture weights are free parameters,
the entropy-regularized optimal transport problem is simplified into
min
W
n
i=1
m
j=1
w i j KL
p i , q j
+
1
λ
w i j log w i j
,
s.t.
w i j ≥ 0,
∀i, ∀ j
m
j=1
w i j =
1
n
,