

96
6 Beyond Point-to-Point Quantum Key Distribution
Alice (Bob) can choose among the decoy intensities {μ 0 , μ 1 } with μ 0 > μ 1 ({ν 0 , ν 1 }
with ν 0 > ν 1 ). To keep the notation simple, we define the following rescaled gains
in the Z basis (where we omit the detection pattern k c , k d ):
˜
Q
μ i ,ν j = e
μ i +ν j p Z Z (k c , k d |μ i , ν j ),
(6.27)
and we rewrite the linear constraints on the yields (6.23) as follows:
˜
Q
μ i ,ν j =
∞
n,m=0
Y nm
n!m!
μ
n
i ν
m
j .
(6.28)
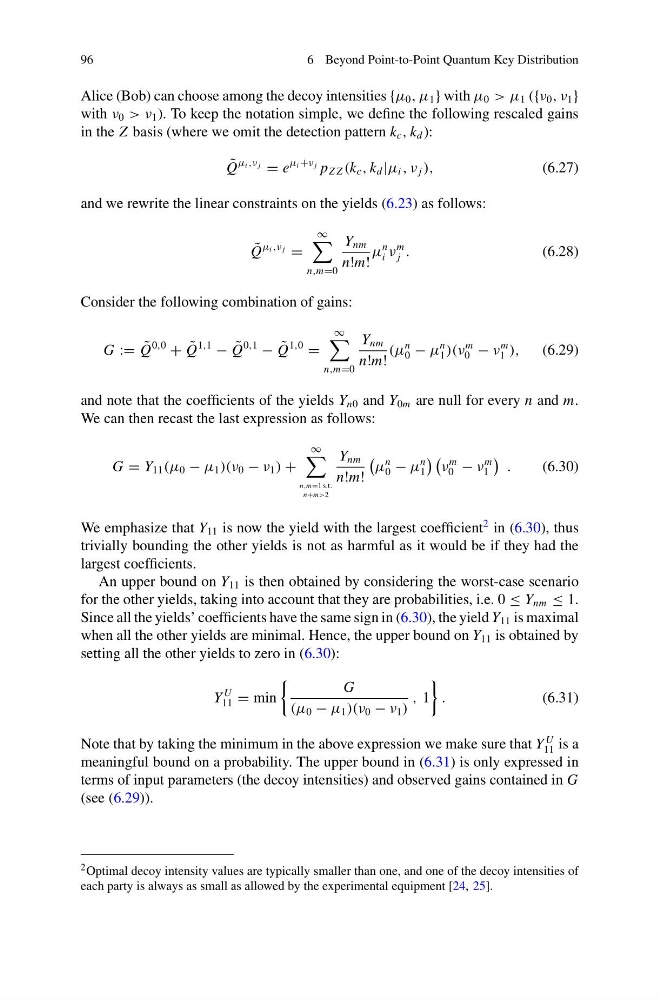
Consider the following combination of gains:
G := ˜
Q
0,0
+ ˜
Q
1,1
− ˜
Q
0,1
− ˜
Q
1,0
=
∞
n,m=0
Y nm
n!m!
(μ
n
0 − μ
n
1 )(ν
m
0 − ν
m
1 ),
(6.29)
and note that the coefficients of the yields Y n0 and Y 0m are null for every n and m.
We can then recast the last expression as follows:
G = Y 11 (μ 0 − μ 1 )(ν 0 − ν 1 ) +
∞
n,m=1 s.t.
n+m>2
Y nm
n!m!
μ
n
0 − μ
n
1
ν
m
0 − ν
m
1
.
(6.30)
We emphasize that Y 11 is now the yield with the largest coefficient
2 in (6.30), thus
trivially bounding the other yields is not as harmful as it would be if they had the
largest coefficients.
An upper bound on Y 11 is then obtained by considering the worst-case scenario
for the other yields, taking into account that they are probabilities, i.e. 0 ≤ Y nm ≤ 1.
Since all the yields’ coefficients have the same sign in (6.30), the yield Y 11 is maximal
when all the other yields are minimal. Hence, the upper bound on Y 11 is obtained by
setting all the other yields to zero in (6.30):
Y
U
11 = min
G
(μ 0 − μ 1 )(ν 0 − ν 1 )
, 1
.
(6.31)
Note that by taking the minimum in the above expression we make sure that Y
U
11 is a
meaningful bound on a probability. The upper bound in (6.31) is only expressed in
terms of input parameters (the decoy intensities) and observed gains contained in G
(see (6.29)).
2 Optimal decoy intensity values are typically smaller than one, and one of the decoy intensities of
each party is always as small as allowed by the experimental equipment [24, 25].