

6 Fundamentals of Filtering
197
The trace operator appears as the quadratic form is a scalar quantity, and its
cyclic property is exploited to obtain the final form. For a detailed derivation, see
Mathai and Provost [41]. In this case, the expected value of the transformed density
depends on the second-order moment of the initial distribution through second-order
derivatives of the nonlinear function g, under the obvious assumption that g is twice
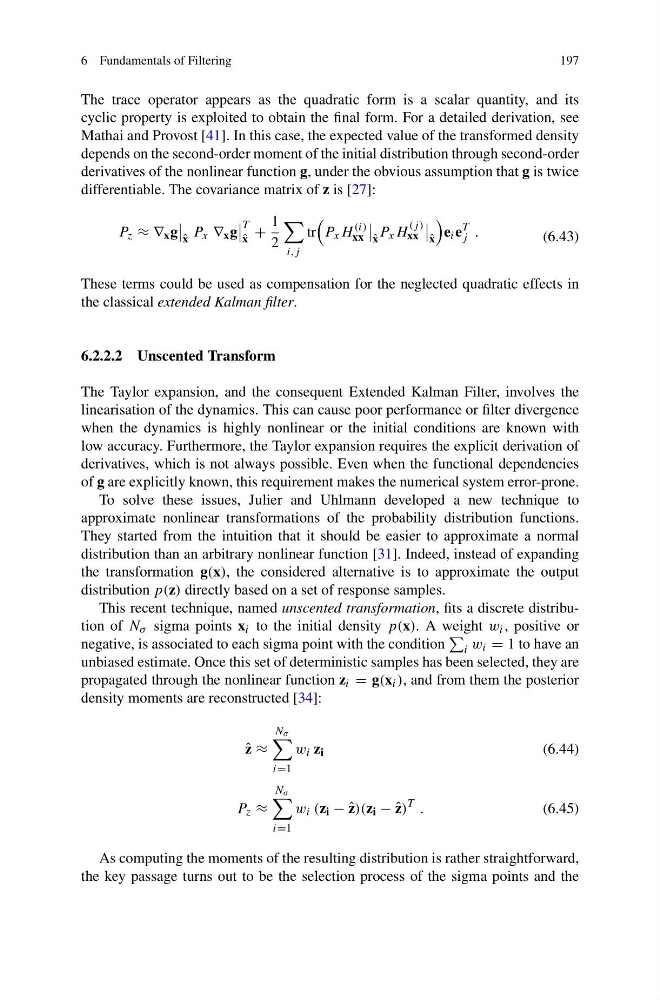
differentiable. The covariance matrix of z is [27]:
P z ≈ ∇ x g
ˆ
x
P x ∇ x g
T
ˆ
x
+
1
2
i,j
tr
P x H
(i)
xx
ˆ
x
P x H
(j )
xx
ˆ
x
e i e
T
j .
(6.43)
These terms could be used as compensation for the neglected quadratic effects in
the classical extended Kalman filter.
6.2.2.2 Unscented Transform
The Taylor expansion, and the consequent Extended Kalman Filter, involves the
linearisation of the dynamics. This can cause poor performance or filter divergence
when the dynamics is highly nonlinear or the initial conditions are known with
low accuracy. Furthermore, the Taylor expansion requires the explicit derivation of
derivatives, which is not always possible. Even when the functional dependencies
of g are explicitly known, this requirement makes the numerical system error-prone.
To solve these issues, Julier and Uhlmann developed a new technique to
approximate nonlinear transformations of the probability distribution functions.
They started from the intuition that it should be easier to approximate a normal
distribution than an arbitrary nonlinear function [31]. Indeed, instead of expanding
the transformation g(x), the considered alternative is to approximate the output
distribution p(z) directly based on a set of response samples.
This recent technique, named unscented transformation, fits a discrete distribution of N σ sigma points x i to the initial density p(x). A weight w i , positive or
negative, is associated to each sigma point with the condition
i w i = 1 to have an
unbiased estimate. Once this set of deterministic samples has been selected, they are
propagated through the nonlinear function z i = g(x i ), and from them the posterior
density moments are reconstructed [34]:
ˆ
z ≈
N σ
i=1
w i z i
(6.44)
P z ≈
N σ
i=1
w i (z i − ˆ
z)(z i − ˆ
z)
T .
(6.45)
As computing the moments of the resulting distribution is rather straightforward,
the key passage turns out to be the selection process of the sigma points and the