

198
C. Greco and M. Vasile
associated weights. In the general approach, this selection process can be seen as
a constrained optimisation problem where the number of samples, the associated
weights and their position are the free variables [10]. The constraints are imposed
to meet the requirement that the discrete distribution, generated by the selected
weights and sigma points, reproduces important statistical characteristics of p(x).
As generally the number of free parameters can be higher than the number of
constraints, the remaining parameters can be used to minimise a penalty function,
e.g. higher-order moments deviation.
This general approach resulted in the birth of numerous variants of unscented
filters. The computational cost of the unscented transformation is proportional to
the number of sigma points employed, so there is a propensity to choose schemes
with only few degrees of freedom. Among them, the simplex unscented approach
requires a minimum number of N x + 1 samples to match the mean and covariance
of a N x dimensional normally distributed random vector x [30, 33]. On the other
hand, additional sigma points can be introduced to reproduce higher-order moments
of a Gaussian distribution, e.g. 2N 2
x + 1 points are required to match up to the
fourth-order moment (kurtosis) with a penalty function minimising the sixth-order
moment [32]. The most used variant relies on the use of 2N x + 1 sigma points [31].
This unscented transformation is able to approximate a Gaussian distribution up to
the third-order, while errors appear as a result of fourth-order cross-kurtoses terms.
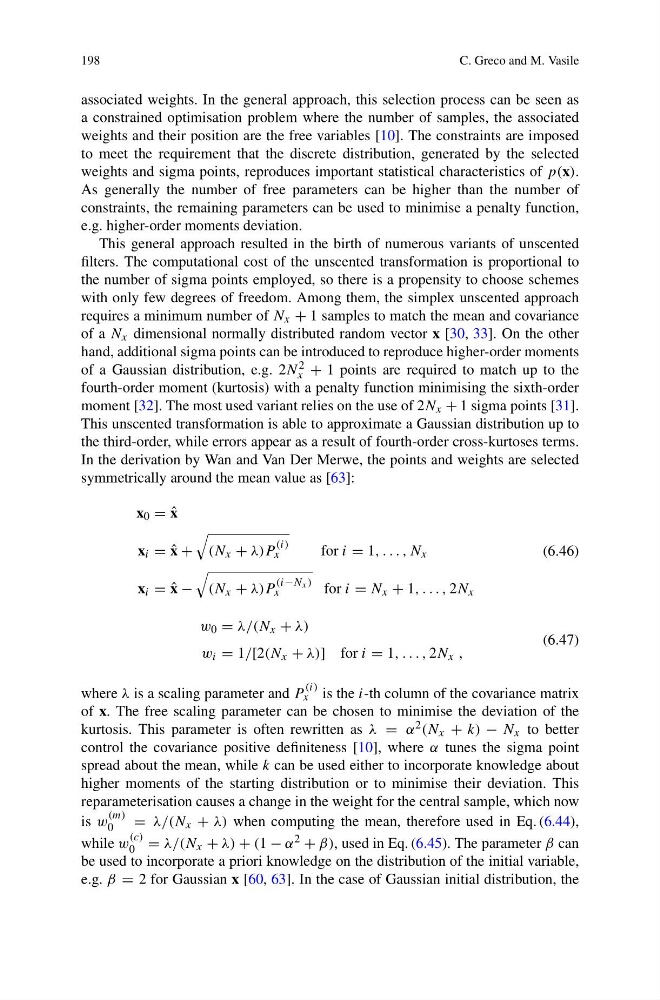
In the derivation by Wan and Van Der Merwe, the points and weights are selected
symmetrically around the mean value as [63]:
x 0 = ˆ
x
x i = ˆ
x +
(N x + λ)P
(i)
x
for i = 1, . . . , N x
x i = ˆ
x −
(N x + λ)P
(i−N x )
x
for i = N x + 1, . . . , 2N x
(6.46)
w 0 = λ/(N x + λ)
w i = 1/[2(N x + λ)] for i = 1, . . . , 2N x ,
(6.47)
where λ is a scaling parameter and P
(i)
x is the i-th column of the covariance matrix
of x. The free scaling parameter can be chosen to minimise the deviation of the
kurtosis. This parameter is often rewritten as λ = α 2 (N x + k) − N x to better
control the covariance positive definiteness [10], where α tunes the sigma point
spread about the mean, while k can be used either to incorporate knowledge about
higher moments of the starting distribution or to minimise their deviation. This
reparameterisation causes a change in the weight for the central sample, which now
is w
(m)
0
= λ/(N x + λ) when computing the mean, therefore used in Eq. (6.44),
while w
(c)
0 = λ/(N x + λ) + (1 − α 2 + β), used in Eq. (6.45). The parameter β can
be used to incorporate a priori knowledge on the distribution of the initial variable,
e.g. β = 2 for Gaussian x [60, 63]. In the case of Gaussian initial distribution, the