

4 Reliability Theory
127
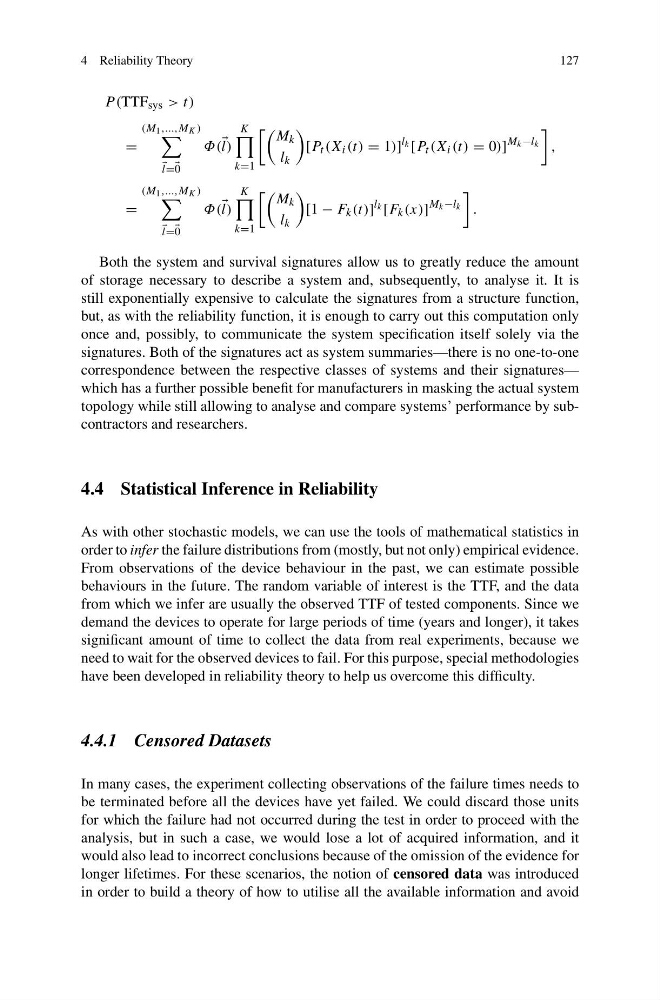
P (TTF sys > t)
=
(M 1 ,...,M K )
l=
0
Φ(
l)
K
k=1
M k
l k
[P t (X i (t) = 1)]
l k [P t (X i (t) = 0)]
M k −l k
,
=
(M 1 ,...,M K )
l=
0
Φ(
l)
K
k=1
M k
l k
[1 − F k (t)]
l k [F k (x)]
M k −l k
.
Both the system and survival signatures allow us to greatly reduce the amount
of storage necessary to describe a system and, subsequently, to analyse it. It is
still exponentially expensive to calculate the signatures from a structure function,
but, as with the reliability function, it is enough to carry out this computation only
once and, possibly, to communicate the system specification itself solely via the
signatures. Both of the signatures act as system summaries—there is no one-to-one
correspondence between the respective classes of systems and their signatures—
which has a further possible benefit for manufacturers in masking the actual system
topology while still allowing to analyse and compare systems’ performance by subcontractors and researchers.
4.4 Statistical Inference in Reliability
As with other stochastic models, we can use the tools of mathematical statistics in
order to infer the failure distributions from (mostly, but not only) empirical evidence.
From observations of the device behaviour in the past, we can estimate possible
behaviours in the future. The random variable of interest is the TTF, and the data
from which we infer are usually the observed TTF of tested components. Since we
demand the devices to operate for large periods of time (years and longer), it takes
significant amount of time to collect the data from real experiments, because we
need to wait for the observed devices to fail. For this purpose, special methodologies
have been developed in reliability theory to help us overcome this difficulty.
4.4.1 Censored Datasets
In many cases, the experiment collecting observations of the failure times needs to
be terminated before all the devices have yet failed. We could discard those units
for which the failure had not occurred during the test in order to proceed with the
analysis, but in such a case, we would lose a lot of acquired information, and it
would also lead to incorrect conclusions because of the omission of the evidence for
longer lifetimes. For these scenarios, the notion of censored data was introduced
in order to build a theory of how to utilise all the available information and avoid