

404
J. Ren et al.
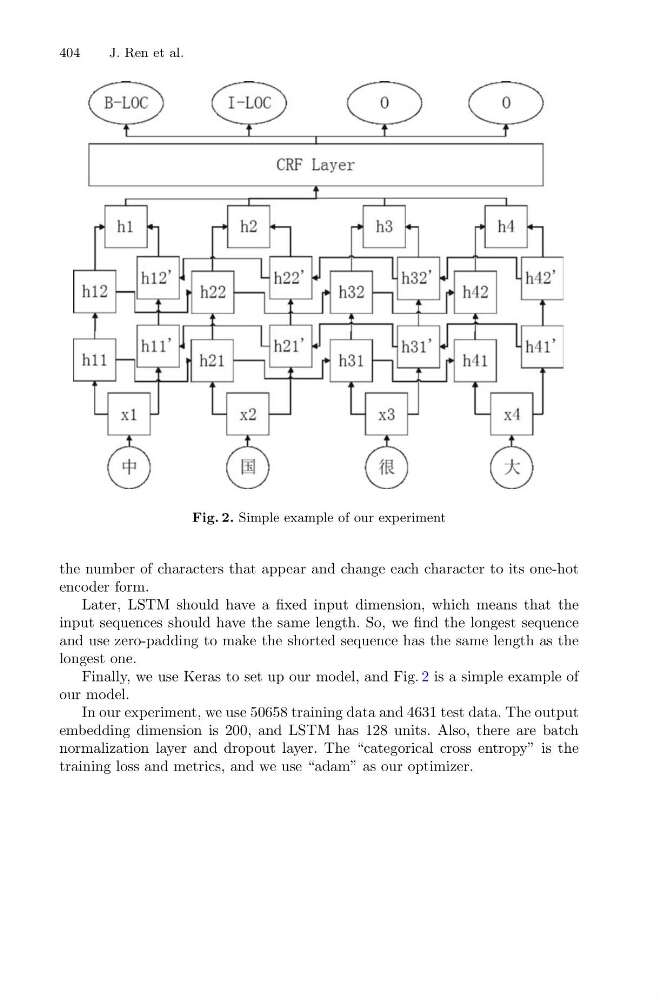
Fig. 2. Simple example of our experiment
the number of characters that appear and change each character to its one-hot
encoder form.
Later, LSTM should have a fixed input dimension, which means that the
input sequences should have the same length. So, we find the longest sequence
and use zero-padding to make the shorted sequence has the same length as the
longest one.
Finally, we use Keras to set up our model, and Fig. 2 is a simple example of
our model.
In our experiment, we use 50658 training data and 4631 test data. The output
embedding dimension is 200, and LSTM has 128 units. Also, there are batch
normalization layer and dropout layer. The “categorical cross entropy” is the
training loss and metrics, and we use “adam” as our optimizer.