

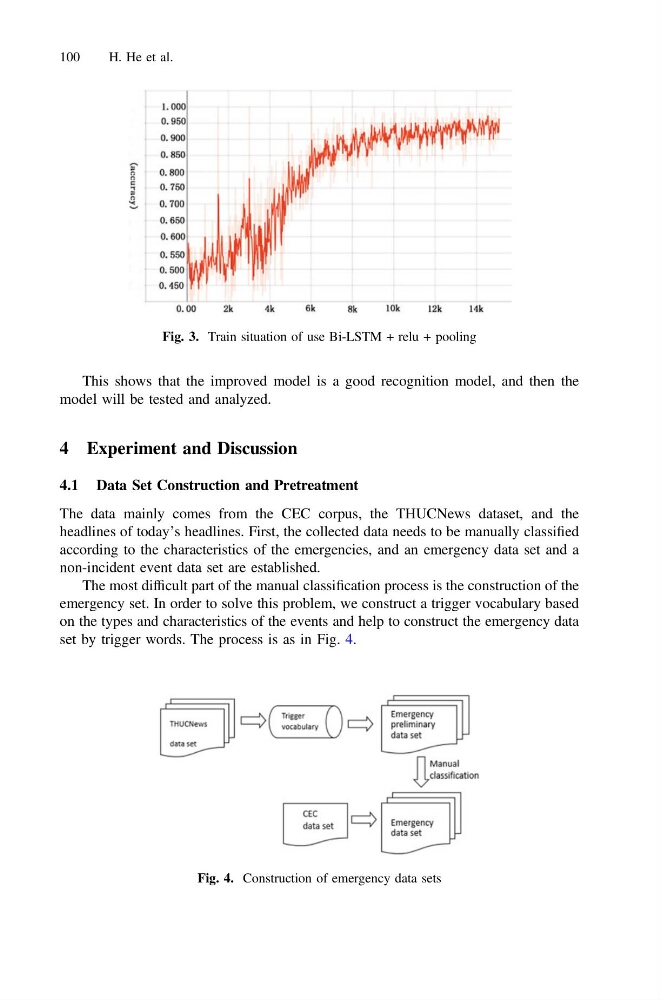
This shows that the improved model is a good recognition model, and then the
model will be tested and analyzed.
4 Experiment and Discussion
4.1 Data Set Construction and Pretreatment
The data mainly comes from the CEC corpus, the THUCNews dataset, and the
headlines of today’s headlines. First, the collected data needs to be manually classified
according to the characteristics of the emergencies, and an emergency data set and a
non-incident event data set are established.
The most difficult part of the manual classification process is the construction of the
emergency set. In order to solve this problem, we construct a trigger vocabulary based
on the types and characteristics of the events and help to construct the emergency data
set by trigger words. The process is as in Fig. 4.
Fig. 3. Train situation of use Bi-LSTM + relu + pooling
Fig. 4. Construction of emergency data sets
100
H. He et al.