

It is agreed within the research community that the cost–benefit scaling of
increasingly power single-processor systems is usually nonlinear and very poor. For
instance, one processor that is twice as fast might cost four times as much, yielding
only half the cost–benefit per pound.
Physics sets its own limit as well—a so-called “thermal barrier” [5]—an amount
of heat that material is capable to dissipate is limited making endless increase of
frequency of operation impossible.
These two arguments are usually applied to justify alternative solutions and
development of parallel designs. There are some drawbacks though, as Amdahl
pointed out, and they are serious.
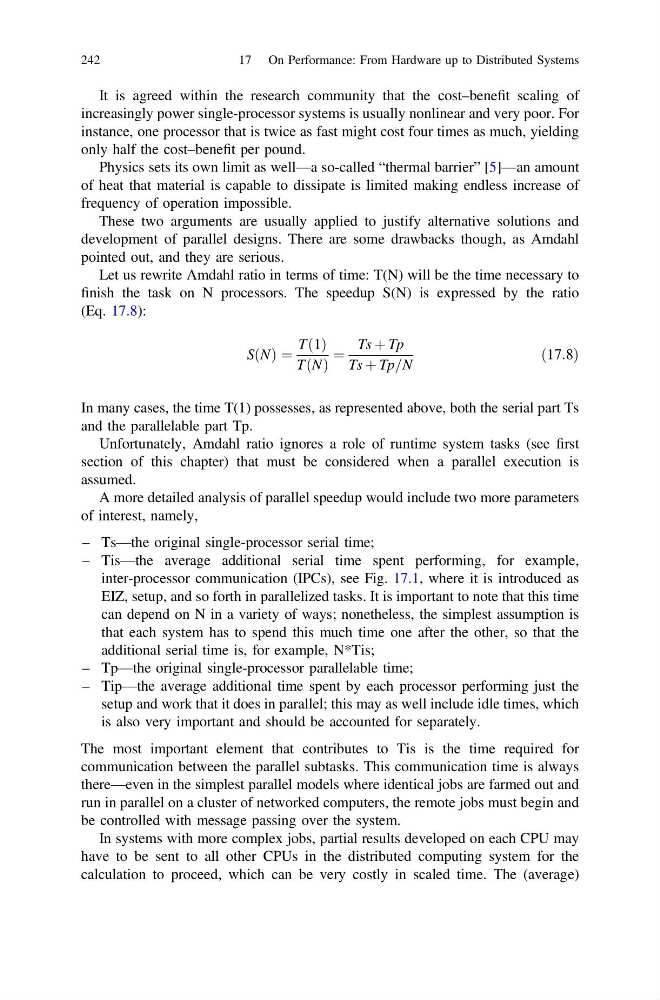
Let us rewrite Amdahl ratio in terms of time: T(N) will be the time necessary to
finish the task on N processors. The speedup S(N) is expressed by the ratio
(Eq. 17.8):
SðNÞ ¼
Tð1Þ
TðNÞ
¼
Ts þ Tp
Ts þ Tp=N
ð17:8Þ
In many cases, the time T(1) possesses, as represented above, both the serial part Ts
and the parallelable part Tp.
Unfortunately, Amdahl ratio ignores a role of runtime system tasks (see first
section of this chapter) that must be considered when a parallel execution is
assumed.
A more detailed analysis of parallel speedup would include two more parameters
of interest, namely,
– Ts—the original single-processor serial time;
– Tis—the average additional serial time spent performing, for example,
inter-processor communication (IPCs), see Fig. 17.1, where it is introduced as
EIZ, setup, and so forth in parallelized tasks. It is important to note that this time
can depend on N in a variety of ways; nonetheless, the simplest assumption is
that each system has to spend this much time one after the other, so that the
additional serial time is, for example, N*Tis;
– Tp—the original single-processor parallelable time;
– Tip—the average additional time spent by each processor performing just the
setup and work that it does in parallel; this may as well include idle times, which
is also very important and should be accounted for separately.
The most important element that contributes to Tis is the time required for
communication between the parallel subtasks. This communication time is always
there—even in the simplest parallel models where identical jobs are farmed out and
run in parallel on a cluster of networked computers, the remote jobs must begin and
be controlled with message passing over the system.
In systems with more complex jobs, partial results developed on each CPU may
have to be sent to all other CPUs in the distributed computing system for the
calculation to proceed, which can be very costly in scaled time. The (average)
242
17 On Performance: From Hardware up to Distributed Systems