

Parallelization of Atomic Image Reconstruction from Holograms
215
4.2 Performance Results of Reconstruction
of Three-dimensional Atomic Images
The reconstruction of three-dimensional atomic images is executed mainly on the
six nested loops of λ, z, x, y, θ , and φ.
The input and output data are stored in three-dimensional arrays of [λ][θ ][φ] =
[21][179][360] and [z][x][y] = [192][192][192], respectively. The output array is
divided in z dimension and distributed among nodes on the PC cluster.
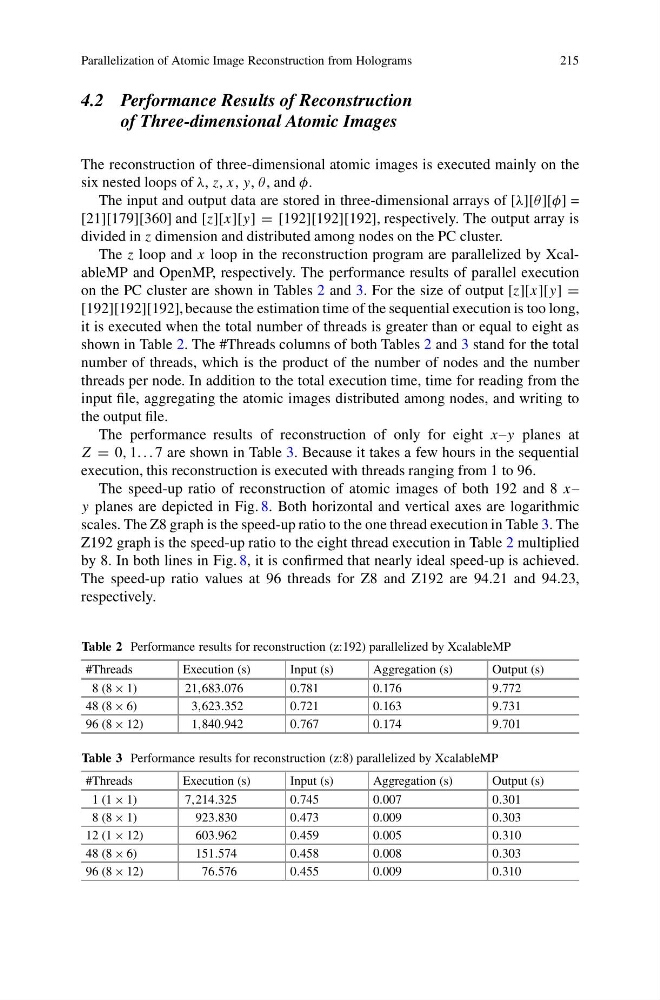
The z loop and x loop in the reconstruction program are parallelized by XcalableMP and OpenMP, respectively. The performance results of parallel execution
on the PC cluster are shown in Tables 2 and 3. For the size of output [z][x][y] =
[192][192][192], because the estimation time of the sequential execution is too long,
it is executed when the total number of threads is greater than or equal to eight as
shown in Table 2. The #Threads columns of both Tables 2 and 3 stand for the total
number of threads, which is the product of the number of nodes and the number
threads per node. In addition to the total execution time, time for reading from the
input file, aggregating the atomic images distributed among nodes, and writing to
the output file.
The performance results of reconstruction of only for eight x–y planes at
Z = 0, 1. . . 7 are shown in Table 3. Because it takes a few hours in the sequential
execution, this reconstruction is executed with threads ranging from 1 to 96.
The speed-up ratio of reconstruction of atomic images of both 192 and 8 x–
y planes are depicted in Fig. 8. Both horizontal and vertical axes are logarithmic
scales. The Z8 graph is the speed-up ratio to the one thread execution in Table 3. The
Z192 graph is the speed-up ratio to the eight thread execution in Table 2 multiplied
by 8. In both lines in Fig. 8, it is confirmed that nearly ideal speed-up is achieved.
The speed-up ratio values at 96 threads for Z8 and Z192 are 94.21 and 94.23,
respectively.
Table 2 Performance results for reconstruction (z:192) parallelized by XcalableMP
#Threads
Execution (s)
Input (s)
Aggregation (s)
Output (s)
8 (8 × 1)
21,683.076
0.781
0.176
9.772
48 (8 × 6)
3,623.352
0.721
0.163
9.731
96 (8 × 12)
1,840.942
0.767
0.174
9.701
Table 3 Performance results for reconstruction (z:8) parallelized by XcalableMP
#Threads
Execution (s)
Input (s)
Aggregation (s)
Output (s)
1 (1 × 1)
7,214.325
0.745
0.007
0.301
8 (8 × 1)
923.830
0.473
0.009
0.303
12 (1 × 12)
603.962
0.459
0.005
0.310
48 (8 × 6)
151.574
0.458
0.008
0.303
96 (8 × 12)
76.576
0.455
0.009
0.310