

216
A. Kubota et al.
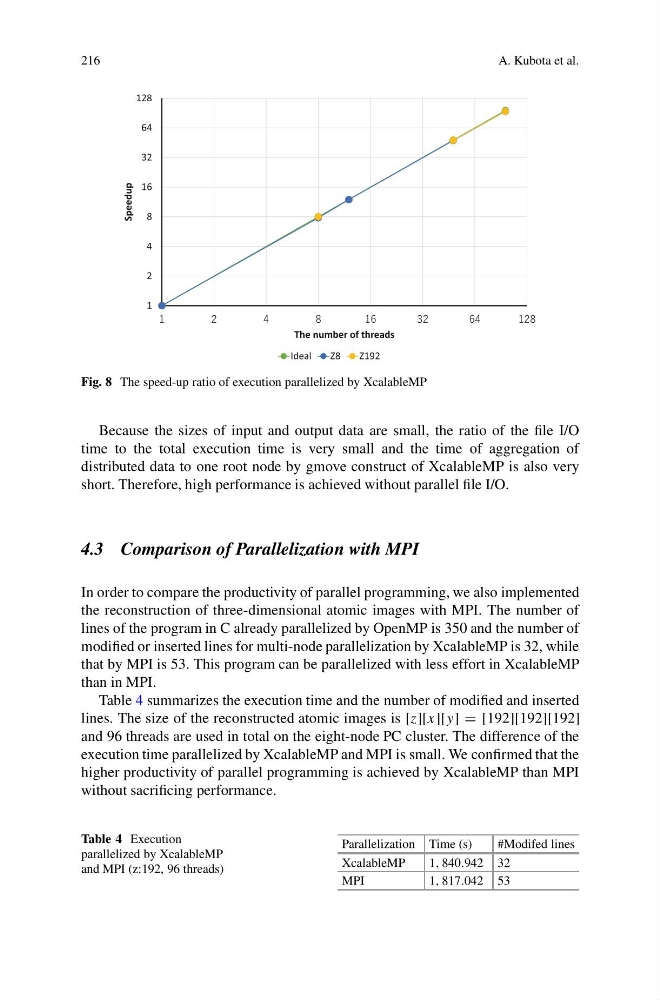
Fig. 8 The speed-up ratio of execution parallelized by XcalableMP
Because the sizes of input and output data are small, the ratio of the file I/O
time to the total execution time is very small and the time of aggregation of
distributed data to one root node by gmove construct of XcalableMP is also very
short. Therefore, high performance is achieved without parallel file I/O.
4.3 Comparison of Parallelization with MPI
In order to compare the productivity of parallel programming, we also implemented
the reconstruction of three-dimensional atomic images with MPI. The number of
lines of the program in C already parallelized by OpenMP is 350 and the number of
modified or inserted lines for multi-node parallelization by XcalableMP is 32, while
that by MPI is 53. This program can be parallelized with less effort in XcalableMP
than in MPI.
Table 4 summarizes the execution time and the number of modified and inserted
lines. The size of the reconstructed atomic images is [z][x][y] = [192][192][192]
and 96 threads are used in total on the eight-node PC cluster. The difference of the
execution time parallelized by XcalableMP and MPI is small. We confirmed that the
higher productivity of parallel programming is achieved by XcalableMP than MPI
without sacrificing performance.
Table 4 Execution
parallelized by XcalableMP
and MPI (z:192, 96 threads)
Parallelization Time (s)
#Modifed lines
XcalableMP
1, 840.942 32
MPI
1, 817.042 53