

214
A. Kubota et al.
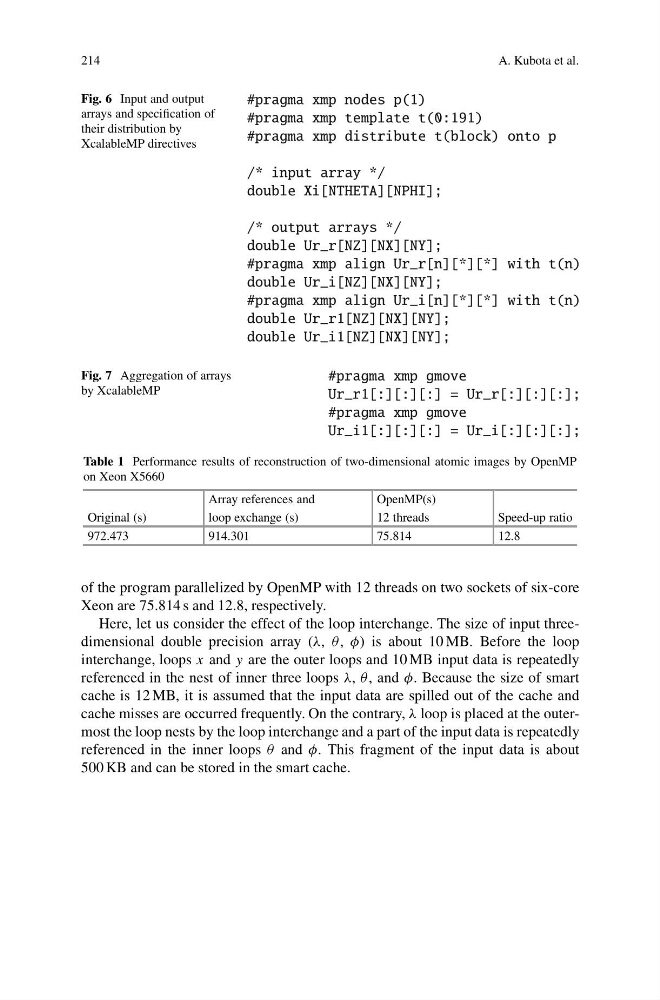
Fig. 6 Input and output
arrays and specification of
their distribution by
XcalableMP directives
Fig. 7 Aggregation of arrays
by XcalableMP
Table 1 Performance results of reconstruction of two-dimensional atomic images by OpenMP
on Xeon X5660
Array references and
OpenMP(s)
Original (s)
loop exchange (s)
12 threads
Speed-up ratio
972.473
914.301
75.814
12.8
of the program parallelized by OpenMP with 12 threads on two sockets of six-core
Xeon are 75.814 s and 12.8, respectively.
Here, let us consider the effect of the loop interchange. The size of input threedimensional double precision array (λ, θ , φ) is about 10 MB. Before the loop
interchange, loops x and y are the outer loops and 10 MB input data is repeatedly
referenced in the nest of inner three loops λ, θ , and φ. Because the size of smart
cache is 12 MB, it is assumed that the input data are spilled out of the cache and
cache misses are occurred frequently. On the contrary, λ loop is placed at the outermost the loop nests by the loop interchange and a part of the input data is repeatedly
referenced in the inner loops θ and φ. This fragment of the input data is about
500 KB and can be stored in the smart cache.