

150
E. A. Thompson
In the days before the existence of genome-wide genetic marker maps, a
comparison of the marker-based Pr(Y|X; ) with Pr(Y; Y ) had a sound foundation
(Smith, 1953; Morton, 1955). However, this is less meaningful when values of
λ or locations j are spread across the genome, and genetic markers are likewise
distributed genome-wide. Further, the unconditional trait probability Pr(Y; Y ) may
not be computable for data observed on very large complex pedigrees or for complex
trait models. Second, even when easily computed, there remains the choice of Y .
Trait models have a number of parameters, for each latent trait locus and genotype.
Maximization over these parameters is often impractical, and the likelihood (6.12)
is often sensitive to model choice. We return to these issues in Sect. 6.4.4 below.
6.4.3 Mapping from IBD in Populations
Just as when the pedigree relationships among individuals are known (Sect. 6.4.1),
population-based IBD mapping relies on excess IBD among individuals of similar
phenotype, relative to some null model or comparison group. As an example, we
consider IBD-based mapping in a case-control study (Browning and Thompson,
2012). To avoid the issues of inferring IBD from marker data, we will assume that
the local IBD between pairs of individuals is known with certainty.
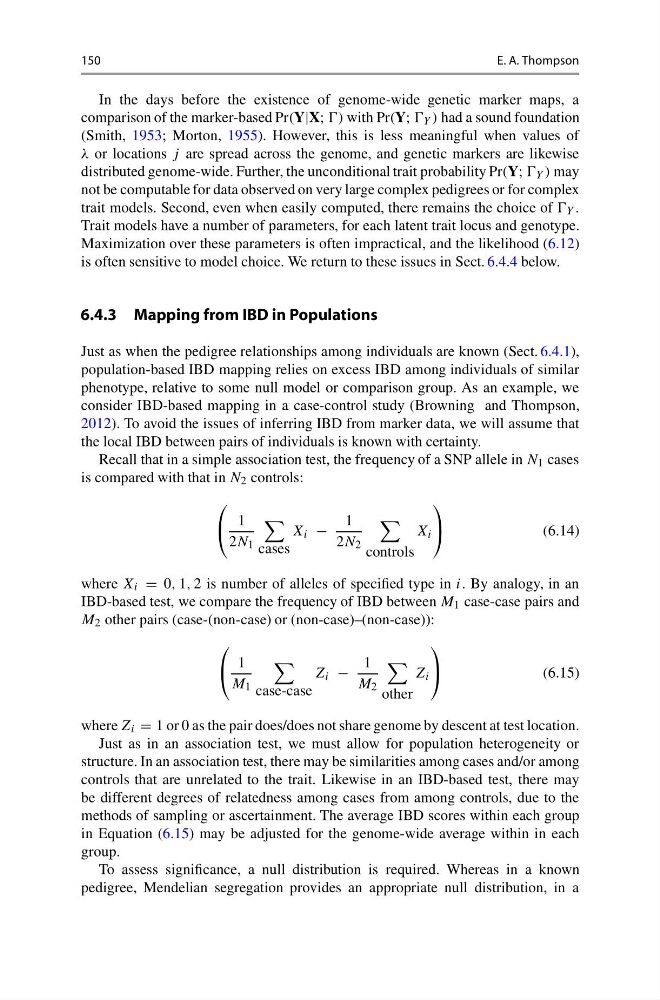
Recall that in a simple association test, the frequency of a SNP allele in N 1 cases
is compared with that in N 2 controls:
⎛
⎝ 1
2N 1
cases
X i −
1
2N 2
controls
X i
⎞
⎠
(6.14)
where X i = 0, 1, 2 is number of alleles of specified type in i. By analogy, in an
IBD-based test, we compare the frequency of IBD between M 1 case-case pairs and
M 2 other pairs (case-(non-case) or (non-case)–(non-case)):
⎛
⎝ 1
M 1
case-case
Z i −
1
M 2
other
Z i
⎞
⎠
(6.15)
where Z i = 1 or 0 as the pair does/does not share genome by descent at test location.
Just as in an association test, we must allow for population heterogeneity or
structure. In an association test, there may be similarities among cases and/or among
controls that are unrelated to the trait. Likewise in an IBD-based test, there may
be different degrees of relatedness among cases from among controls, due to the
methods of sampling or ascertainment. The average IBD scores within each group
in Equation (6.15) may be adjusted for the genome-wide average within in each
group.
To assess significance, a null distribution is required. Whereas in a known
pedigree, Mendelian segregation provides an appropriate null distribution, in a