

138
5: Mahesh Pal, Pakorn Watanachaturaporn
the two terms in (5.4). First is the empirical risk and second is the confidence
term, which depends on the VC-dimension of the set of functions. SRM minimizes the expected risk function with respect to both the empirical risk and
the VC-dimension. To achieve this aim, a nested structure of hypothesis space
is introduced by dividing the entire class of functions into nested subsets
HI C H2 C ... C Hn C ....
(5.6)
The symbol C indicates "is contained in." Each hypothesis space has the
property that h(n) ::: h(n + 1) where h(n) is the VC-dimension of the set Hn.
This implies that the VC-dimension of each hypothesis space is finite. The
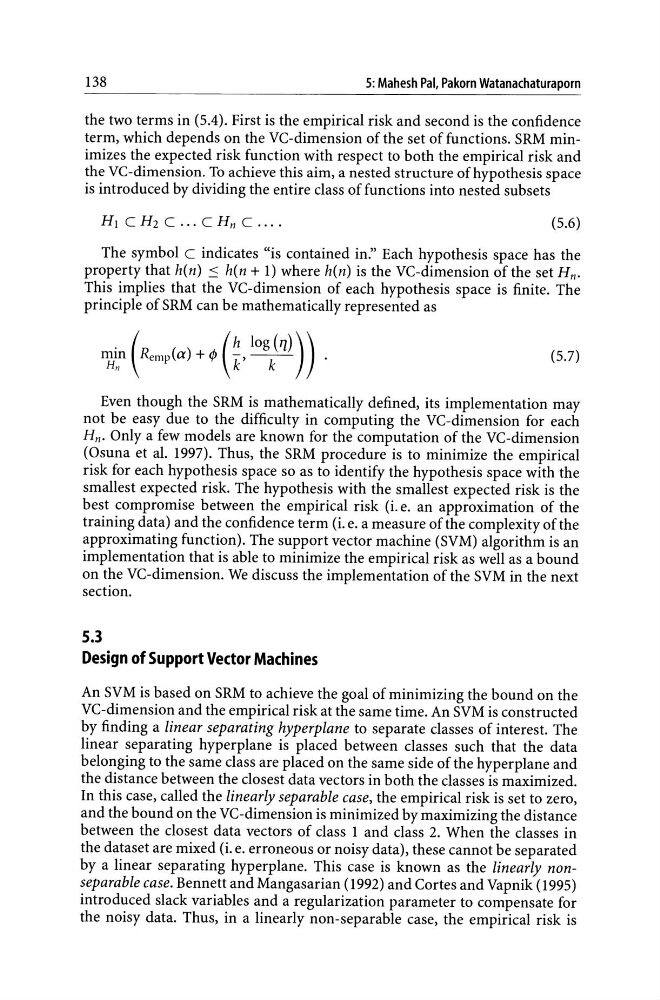
principle of SRM can be mathematically represented as
. (
(h log ('1) ))
~~n Remp(a) + l /J k' - k - .
(5.7)
Even though the SRM is mathematically defined, its implementation may
not be easy due to the difficulty in computing the VC-dimension for each
Hn. Only a few models are known for the computation of the VC-dimension
(Osuna et al. 1997). Thus, the SRM procedure is to minimize the empirical
risk for each hypothesis space so as to identify the hypothesis space with the
smallest expected risk. The hypothesis with the smallest expected risk is the
best compromise between the empirical risk (i. e. an approximation of the
training data) and the confidence term (i. e. a measure of the complexity of the
approximating function). The support vector machine (SVM) algorithm is an
implementation that is able to minimize the empirical risk as well as a bound
on the VC-dimension. We discuss the implementation of the SVM in the next
section.
S.3
Design of Support Vector Machines
An SVM is based on SRM to achieve the goal of minimizing the bound on the
VC-dimension and the empirical risk at the same time. An SVM is constructed
by finding a linear separating hyperplane to separate classes of interest. The
linear separating hyperplane is placed between classes such that the data
belonging to the same class are placed on the same side of the hyperplane and
the distance between the closest data vectors in both the classes is maximized.
In this case, called the linearly separable case, the empirical risk is set to zero,
and the bound on the VC-dimension is minimized by maximizing the distance
between the closest data vectors of class 1 and class 2. When the classes in
the dataset are mixed (i. e. erroneous or noisy data), these cannot be separated
by a linear separating hyperplane. This case is known as the linearly nonseparable case. Bennett and Mangasarian (1992) and Cortes and Vapnik (1995)
introduced slack variables and a regularization parameter to compensate for
the noisy data. Thus, in a linearly non-separable case, the empirical risk is