

116
Matt Duckham and Mike Worboys
Extensional Form
A key concept in the development of a rosetta system is to consider categories in geographical ontologies in their extensional form. The extensional form of a category
is the set of all instances of that category. For example, one way to describe what
is meant by the category “Car” is to refer to the set of all objects that we call cars.
Subcategories, such as “Tan-colored Chevrolet Lumina,” will contain only a subset
of those objects. Using the extensional form of a category makes explicit the link
between extensional and intensional information, enabling an automated computational system to manipulate categories without any requirement to understand the
semantics of that category.
Reasoning System
An initially attractive route to realizing a rosetta system, such as described informally above, is to formalize the rules required for the inductive inference process,
and then implement those rules within an automated reasoning system. We might
start by representing a taxonomy as a partially ordered set (C, ≤), where C is a set
of categories and ≤ is the ordering (subsumption relationships) on those categories.
Now, a geographical data set can be represented as a set S that is a partition of a
region of space, a taxonomy (C, ≤), and a function e : C → 2
S that defines which
spatial regions are labeled with which categories (2
S is the power set of S ). Thus, e
associates each category in the taxonomy with a unique set of elements from the partition of space S . We call e an extension function because it provides the extensional
form of each category within the context of its data set.
To illustrate, for data set A in Fig. 6.1 the taxonomy (C A , ≤ A ) is represented by hierarchy of categories; the partition of space S A is represented by the map itself, comprised of jointly exhaustive and pairwise disjoint regions; and the extension function
e A is represented by the labels on both the taxonomy and the map (i.e. for each category we can identify on the map the set of locations that are labeled as that category).
From this basis, it is possible to start to define simple first-order logical rules
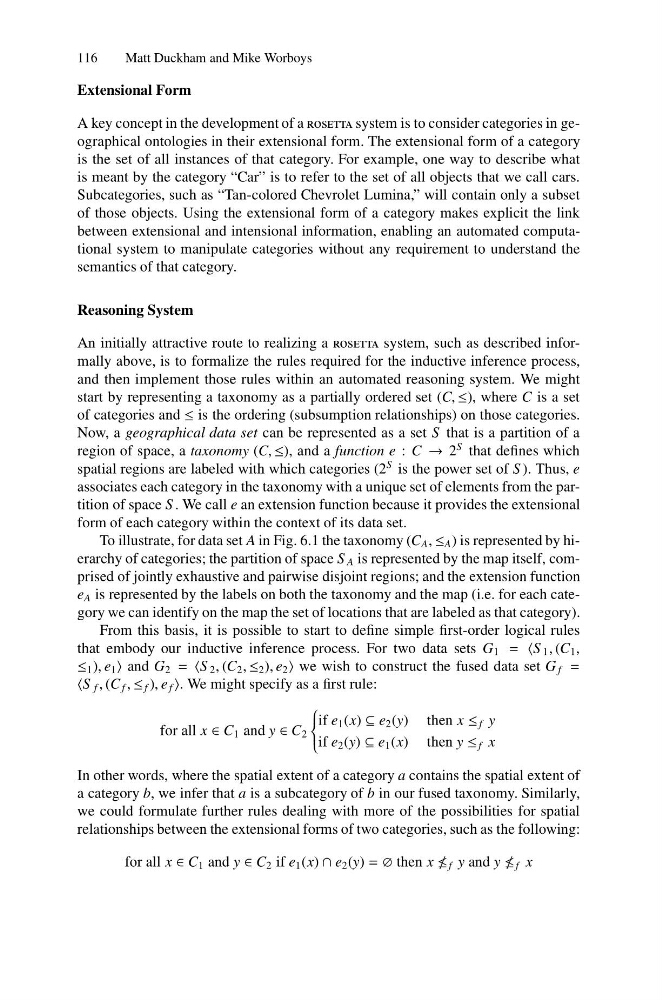
that embody our inductive inference process. For two data sets G 1 = S 1 , (C 1 ,
≤ 1 ), e 1 and G 2 = S 2 , (C 2 , ≤ 2 ), e 2 we wish to construct the fused data set G f =
f , (C f , ≤ f ), e f . We might specify as a first rule:
for all x ∈ C 1 and y ∈ C 2
⎧
⎪ ⎪ ⎨
⎪ ⎪ ⎩
if e 1 (x) ⊆ e 2 (y) then x ≤ f y
if e 2 (y) ⊆ e 1 (x) then y ≤ f x
In other words, where the spatial extent of a category a contains the spatial extent of
a category b, we infer that a is a subcategory of b in our fused taxonomy. Similarly,
we could formulate further rules dealing with more of the possibilities for spatial
relationships between the extensional forms of two categories, such as the following:
for all x ∈ C 1 and y ∈ C 2 if e 1 (x) ∩ e 2 (y) = ∅ then x f y and y f x