

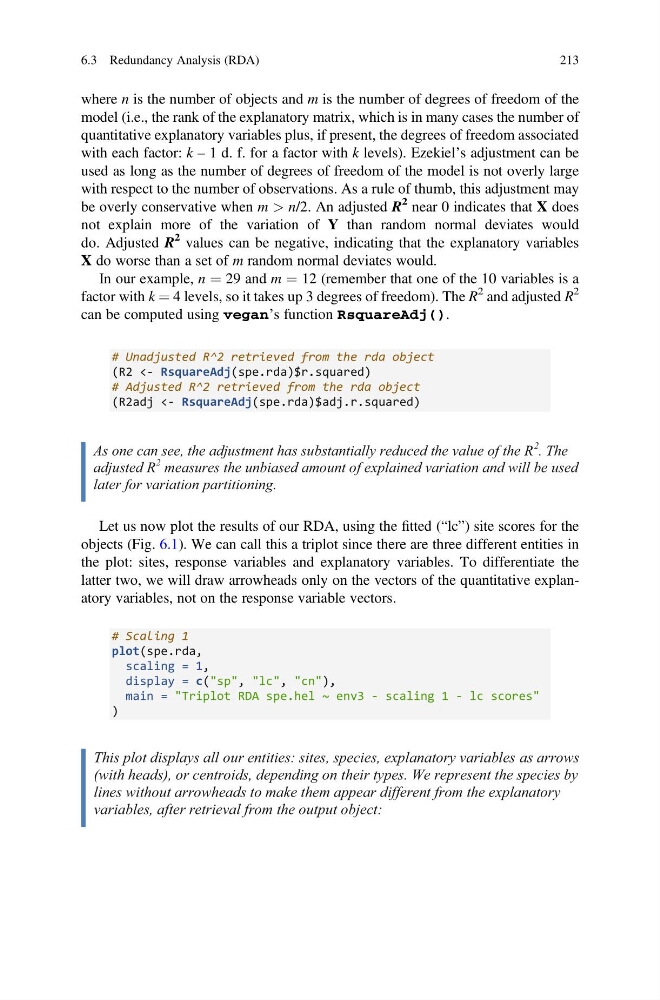
where n is the number of objects and m is the number of degrees of freedom of the
model (i.e., the rank of the explanatory matrix, which is in many cases the number of
quantitative explanatory variables plus, if present, the degrees of freedom associated
with each factor: k – 1 d. f. for a factor with k levels). Ezekiel’s adjustment can be
used as long as the number of degrees of freedom of the model is not overly large
with respect to the number of observations. As a rule of thumb, this adjustment may
be overly conservative when m > n/2. An adjusted R
2 near 0 indicates that X does
not explain more of the variation of Y than random normal deviates would
do. Adjusted R
2 values can be negative, indicating that the explanatory variables
X do worse than a set of m random normal deviates would.
In our example, n ¼ 29 and m ¼ 12 (remember that one of the 10 variables is a
factor with k ¼ 4 levels, so it takes up 3 degrees of freedom). The R
2 and adjusted R
2
can be computed using vegan’s function RsquareAdj().
# Unadjusted R^2 retrieved from the rda object
(R2 <- RsquareAdj(spe.rda)$r.squared)
# Adjusted R^2 retrieved from the rda object
(R2adj <- RsquareAdj(spe.rda)$adj.r.squared)
As one can see, the adjustment has substantially reduced the value of the R
2
. The
adjusted R
2 measures the unbiased amount of explained variation and will be used
later for variation partitioning.
Let us now plot the results of our RDA, using the fitted (“lc”) site scores for the
objects (Fig. 6.1). We can call this a triplot since there are three different entities in
the plot: sites, response variables and explanatory variables. To differentiate the
latter two, we will draw arrowheads only on the vectors of the quantitative explanatory variables, not on the response variable vectors.
# Scaling 1
plot(spe.rda,
scaling = 1,
display = c("sp", "lc", "cn"),
main = "Triplot RDA spe.hel ~ env3 - scaling 1 - lc scores"
)
This plot displays all our entities: sites, species, explanatory variables as arrows
(with heads), or centroids, depending on their types. We represent the species by
lines without arrowheads to make them appear different from the explanatory
variables, after retrieval from the output object:
6.3 Redundancy Analysis (RDA)
213