

7 Land-use and Catchment Characteristics
147
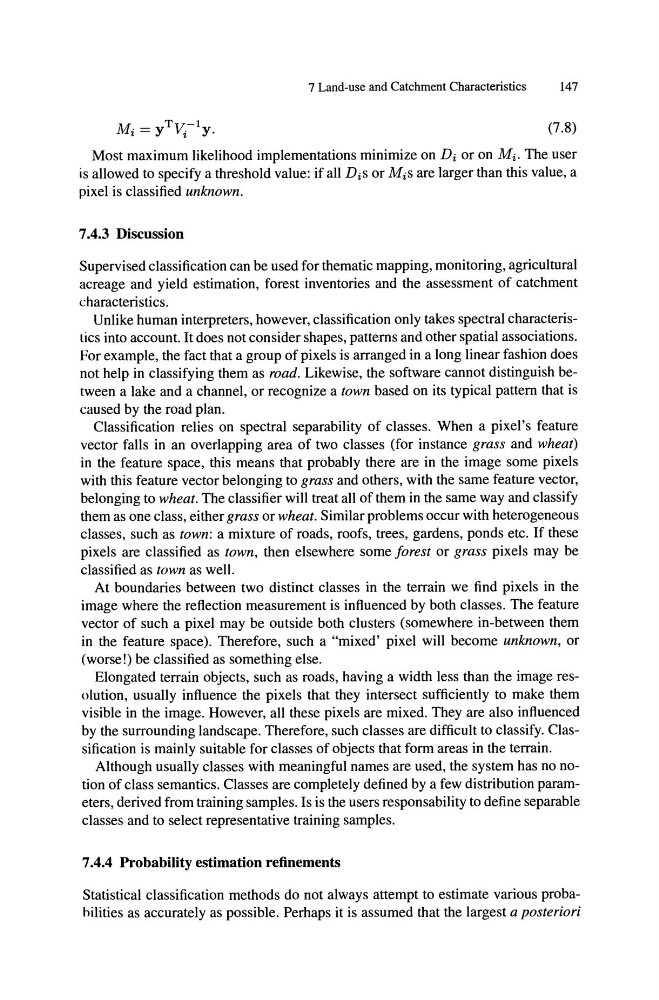
M
TV-l
i = Y i y.
(7.8)
Most maximum likelihood implementations minimize on Di or on Mi. The user
is allowed to specify a threshold value: if all DiS or MiS are larger than this value, a
pixel is classified unknown.
7.4.3 Discussion
Supervised classification can be used for thematic mapping, monitoring, agricultural
acreage and yield estimation, forest inventories and the assessment of catchment
characteristics.
Unlike human interpreters, however, classification only takes spectral characteristics into account. It does not consider shapes, patterns and other spatial associations.
For example, the fact that a group of pixels is arranged in a long linear fashion does
not help in classifying them as road. Likewise, the software cannot distinguish between a lake and a channel, or recognize a town based on its typical pattern that is
caused by the road plan.
Classification relies on spectral separability of classes. When a pixel's feature
vector falls in an overlapping area of two classes (for instance grass and wheat)
in the feature space, this means that probably there are in the image some pixels
with this feature vector belonging to grass and others, with the same feature vector,
belonging to wheat. The classifier will treat all of them in the same way and classify
them as one class, either grass or wheat. Similar problems occur with heterogeneous
classes, such as town: a mixture of roads, roofs, trees, gardens, ponds etc. If these
pixels are classified as town, then elsewhere some forest or grass pixels may be
classified as town as well.
At boundaries between two distinct classes in the terrain we find pixels in the
image where the reflection measurement is influenced by both classes. The feature
vector of such a pixel may be outside both clusters (somewhere in-between them
in the feature space). Therefore, such a "mixed' pixel will become unknown, or
(worse!) be classified as something else.
Elongated terrain objects, such as roads, having a width less than the image resolution, usually influence the pixels that they intersect sufficiently to make them
visible in the image. However, all these pixels are mixed. They are also influenced
by the surrounding landscape. Therefore, such classes are difficult to classify. Classification is mainly suitable for classes of objects that form areas in the terrain.
Although usually classes with meaningful names are used, the system has no notion of class semantics. Classes are completely defined by a few distribution parameters, derived from training samples. Is is the users responsability to define separable
classes and to select representative training samples.
7.4.4 Probability estimation refinements
Statistical classification methods do not always attempt to estimate various probahilities as accurately as possible. Perhaps it is assumed that the largest a posteriori