

Atmospheric Data Assimilation and Quality Control
93
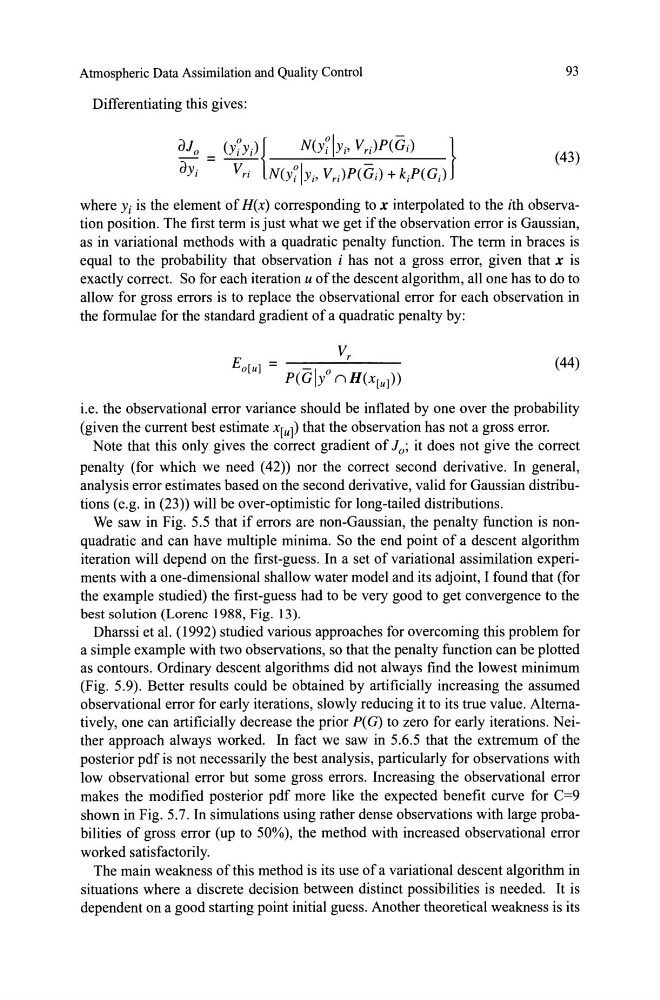
Differentiating this gives:
dlo
(Y~Yi){
N(lIYi' Vri)P(Gi)
}
dYi = ~ N(y~IYi' Vr;)P(Gi) + kjP(G;)
(43)
where Yi is the element of H(x) corresponding to x interpolated to the ith observation position. The first term is just what we get if the observation error is Gaussian,
as in variational methods with a quadratic penalty function. The term in braces is
equal to the probability that observation i has not a gross error, given that x is
exactly correct. So for each iteration U ofthe descent algorithm, alI one has to do to
alIow for gross errors is to replace the observational error for each observation in
the formulae for the standard gradient of a quadratic penalty by:
Eo[ul =
I o
P(G Y nH(x[ul»
V r
(44)
i.e. the observational error variance should be inflated by one over the probability
(given the current best estimate x[u]) that the observation has not a gross error.
Note that this only gives the correct gradient of 1 0 ; it does not give the correct
penalty (for which we need (42» nor the correct second derivative. In general,
analysis error estimates based on the second derivative, valid for Gaussian distributions (e.g. in (23» will be over-optimistic for long-tailed distributions.
We saw in Fig. 5.5 that if errors are non-Gaussian, the penalty function is nonquadratic and can have multiple minima. So the end point of a descent algorithm
iteration will depend on the first-guess. In a set of variational assimilation experiments with a one-dimensional shalIow water model and its adjoint, I found that (for
the example studied) the first-guess had to be very good to get convergence to the
best solution (Lorenc 1988, Fig. 13).
Dharssi et al. (1992) studied various approaches for overcoming this problem for
a simple example with two observations, so that the penalty function can be plotted
as contours. Ordinary descent algorithms did not always find the lowest minimum
(Fig. 5.9). Better results could be obtained by artificially increasing the assumed
observational error for early iterations, slowly reducing it to its true value. Altematively, one can artificially decrease the prior P(G) to zero for early iterations. Neither approach always worked. In fact we saw in 5.6.5 that the extremum of the
posterior pdf is not necessarily the best analysis, particularly for observations with
low observational error but some gross errors. Increasing the observational error
makes the modified posterior pdf more like the expected benefit curve for C=9
shown in Fig. 5.7. In simulations using rather dense observations with large probabilities of gross error (up to 50%), the method with increased observational error
worked satisfactorily.
The main weakness of this method is its use of a variational descent algorithm in
situations where a discrete decision between distinct possibilities is needed. It is
dependent on a good starting point initial guess. Another theoretical weakness is its