

Section 2.3: Neglecting Serial Correlation
17
becomes conservative - and when the "equivalent sampie size" is "optimized"
the test becomes liberal 2 . We discuss this case in detail in Section 2.4.
There are, however, again and again cases in which people simply ignore
this condition, in particular when dealing with more exotic tests such as the
Mann-Kendall test, which is used to reject the null hypothesis of "no trends".
To demonstrate that the result of such a test really depends strongly on the
autocorrelation, Kulkarni and von Storch (1995) made aseries of Monte Carlo
experiments with AR(l)-processes with different values of the parameter a.
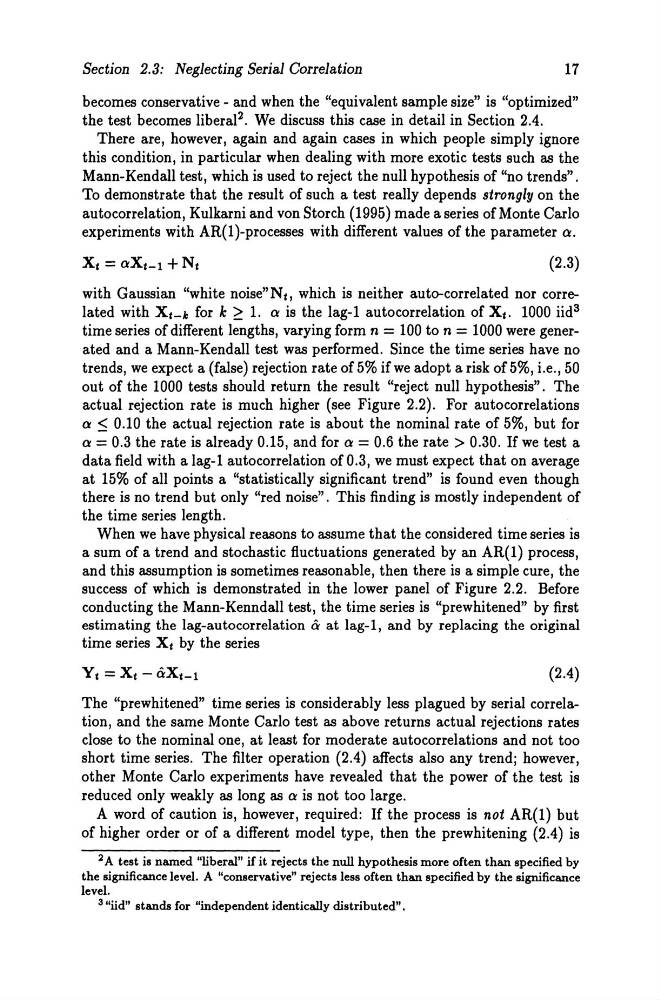
(2.3)
with Gaussian "white noise"Nt , which is neither auto-correlated nor correlated with Xt-k for k 2:: 1. a is the lag-1 autocorrelation of X t . 1000 iid 3
time series of different lengths, varying form n = 100 to n = 1000 were generated and a Mann-Kendall test was performed. Since the time series have no
trends, we expect a (false) rejection rate of 5% ifwe adopt a risk of 5%, i.e., 50
out of the 1000 tests should return the result "reject null hypothesis" . The
actual rejection rate is much higher (see Figure 2.2). For autocorrelations
a ~ 0.10 the actual rejection rate is about the nominal rate of 5%, but for
a = 0.3 the rate is already 0.15, and for a = 0.6 the rate> 0.30. If we test a
data field with a lag-1 autocorrelation of 0.3, we must expect that on average
at 15% of all points a "statistically significant trend" is found even though
there is no trend but only "red noise". This finding is mostly independent of
the time series length.
When we have physical reasons to assurne that the considered time series is
a sum of a trend and stochastic fluctuations generated by an AR(l) process,
and this assumption is sometimes reasonable, then there is a simple eure, the
success of which is demonstrated in the lower panel of Figure 2.2. Before
conducting the Mann-Kenndall test, the time series is "prewhitened" by first
estimating the lag-autocorrelation & at lag-I, and by replacing the original
time series X t by the series
(2.4)
The "prewhitened" time series is considerably less plagued by serial correlation, and the same Monte Carlo test as above returns actual rejections rates
elose to the nominal one, at least for moderate autocorrelations and not too
short time series. The filter operation (2.4) affects also any trend; however,
other Monte Carlo experiments have revealed that the power of the test is
reduced only weakly as long as a is not too large.
A word of caution is, however, required: If the process is not AR(l) but
of higher order or of a different model type, then the prewhitening (2.4) is
2 A test is named "liberal" if it rejects the null hypothesis more olten than specified by
the significance level. A "conservative" rejects less olten than specified by the significance
level.
3 "lid" stands for "independent identically distributed" .