

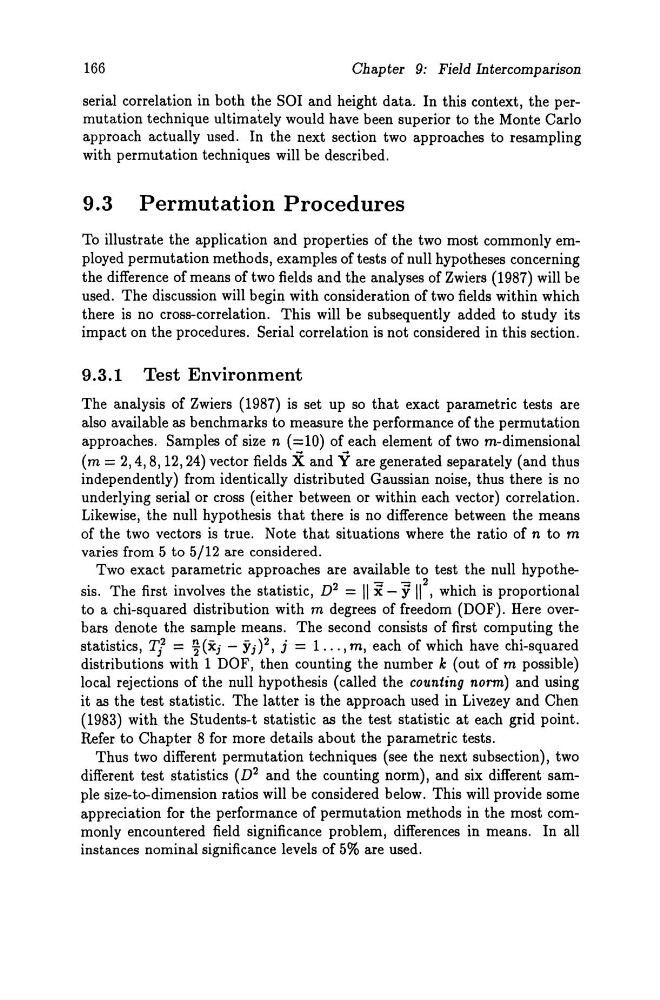
166
Chapter 9: Field Intercomparison
serial correlation in both the SOl and height data. In this context, the permutation technique ultimately would have been superior to the Monte Carlo
approach actually used. In the next section two approaches to resampling
with permutation techniques will be described.
9.3 Permutation Procedures
To illustrate the application and properties of the two most commonly employed permutation methods, examples of tests of null hypotheses concerning
the difference of means of two fields and the analyses of Zwiers (1987) will be
used. The discussion will begin with consideration of two fields within which
there is no cross-correlation. This will be subsequently added to study its
impact on the procedures. Serial correlation is not considered in this section.
9.3.1 Test Environment
The analysis of Zwiers (1987) is set up so that exact parametric tests are
also available as benchmarks to measure the performance of the permutation
approaches. Sampies of size n (=10) of each element of two m-dimensional
(m = 2,4,8,12,24) vector fields X and Y are generated separately (and thus
independently) from identically distributed Gaussian noise, thus there is no
underlying serial or cross (either between or within each vector) correlation.
Likewise, the null hypothesis that there is no difference between the means
of the two vectors is true. Note that situations where the ratio of n to m
varies from 5 to 5/12 are considered.
Two exact parametric approaches are available to test the null hypothesis. The first involves the statistic, D 2 = 11 i - Y 11
2 , which is proportional
to a chi-squared distribution with m degrees of freedom (DOF). Here overbars denote the sampie means. The second consists of first computing the
statistics, Tl = ~(Xj - Yj?, j = 1 ... , m, each of which have chi-squared
distributions with 1 DOF, then counting the number k (out of m possible)
local rejections of the null hypothesis (called the counting norm) and using
it as the test statistic. The latter is the approach used in Livezey and Chen
(1983) with the Students-t statistic as the test statistic at each grid point.
Refer to Chapter 8 for more details about the parametric tests.
Thus two different permutation techniques (see the next subsection), two
different test statistics (D 2 and the counting norm), and six different sampIe size-to-dimension ratios will be considered below. This will provide some
appreciation for the performance of permutation methods in the most commonly encountered field significance problem, differences in means. In all
instances nominal significance levels of 5% are used.