

Introduction to Numerical Weather Prediction Data Assimilation
85
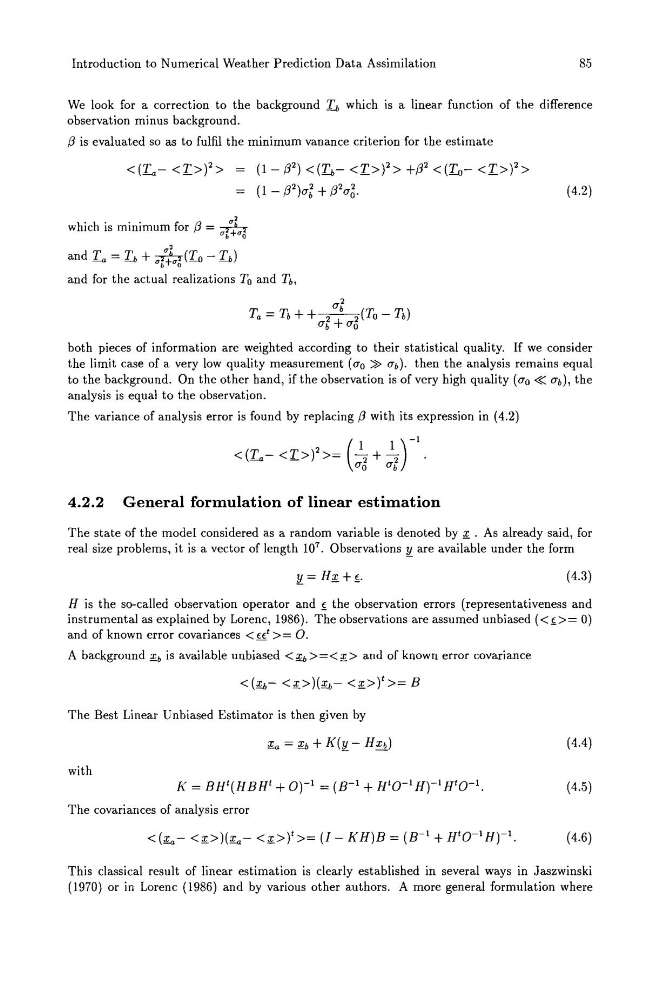
We look for a correction to the background L which is a linear function of the difference
observation minus background.
{3 is evaluated so as to fulfil the minimum vanance criterion for the estimate
2
which is minimum for {3 = ~+ O"b (10
,,2
andL=L+~+ (Io-L)
(7b 0'0
(1 - {32) < (L- +{32 < (Io-
(1 - {32)er~ + {32 er6.
and for the actual realizations To and n,
er~
Ta = n + +-2--2 (To - n)
erb + era
(4.2)
both pieces of information are weighted according to their statistical quality. If we consider
the limit case of a very low quality measurement (era» erb). then the analysis remains equal
to the background. On the other hand, if the observation is of very high quality (era « erb), the
analysis is equal to the observation.
The variance of analysis error is found by replacing {3 with its expression in (4.2)
(
1
1 )-1
«L-= 2" + 2"
era
erb
4.2.2 General formulation of linear estimation
The state of the model considered as a random variable is denoted by if . As already said, for
real size problems, it is a vector of length 10 7 . Observations lL are available under the form
( 4.3)
H is the so-called observation operator and f the observation errors (representativeness and
instrumental as explained by Lorenc, 1986). The observations are assumed unbiased « f>= 0)
and of known error covariances= o.
A background ifb is available unbiased=< if> and of known error covariance
The Best Linear Unbiased Estimator is then given by
(4.4)
with
( 4.5)
The covariances of analysis error
This classical result of linear estimation is clearly established in several ways in Jaszwinski
(1970) or in Lorenc (1986) and by various other authors. A more general formulation where
85
We look for a correction to the background L which is a linear function of the difference
observation minus background.
{3 is evaluated so as to fulfil the minimum vanance criterion for the estimate
2
which is minimum for {3 = ~+ O"b (10
,,2
andL=L+~+ (Io-L)
(7b 0'0
(1 - {32) < (L-
(1 - {32)er~ + {32 er6.
and for the actual realizations To and n,
er~
Ta = n + +-2--2 (To - n)
erb + era
(4.2)
both pieces of information are weighted according to their statistical quality. If we consider
the limit case of a very low quality measurement (era» erb). then the analysis remains equal
to the background. On the other hand, if the observation is of very high quality (era « erb), the
analysis is equal to the observation.
The variance of analysis error is found by replacing {3 with its expression in (4.2)
(
1
1 )-1
«L-
era
erb
4.2.2 General formulation of linear estimation
The state of the model considered as a random variable is denoted by if . As already said, for
real size problems, it is a vector of length 10 7 . Observations lL are available under the form
( 4.3)
H is the so-called observation operator and f the observation errors (representativeness and
instrumental as explained by Lorenc, 1986). The observations are assumed unbiased « f>= 0)
and of known error covariances
A background ifb is available unbiased
The Best Linear Unbiased Estimator is then given by
(4.4)
with
( 4.5)
The covariances of analysis error
This classical result of linear estimation is clearly established in several ways in Jaszwinski
(1970) or in Lorenc (1986) and by various other authors. A more general formulation where