

174
11 Optimal Control Theory
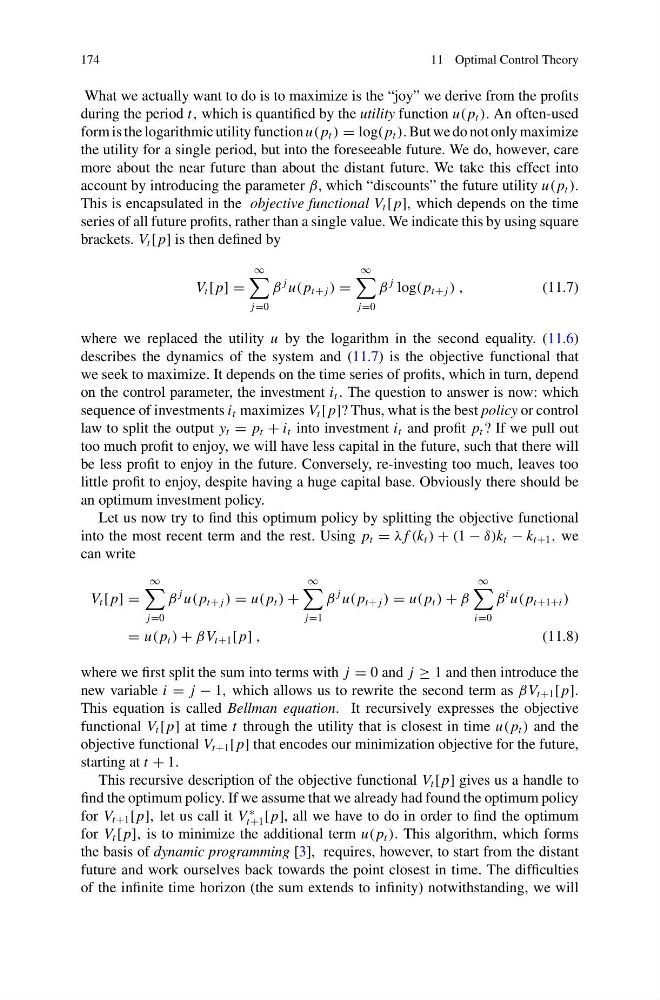
What we actually want to do is to maximize is the “joy” we derive from the profits
during the period t, which is quantified by the utility function u( p t ). An often-used
form is the logarithmic utility function u( p t ) = log( p t ). But we do not only maximize
the utility for a single period, but into the foreseeable future. We do, however, care
more about the near future than about the distant future. We take this effect into
account by introducing the parameter β, which “discounts” the future utility u( p t ).
This is encapsulated in the objective functional V t [ p], which depends on the time
series of all future profits, rather than a single value. We indicate this by using square
brackets. V t [ p] is then defined by
V t [ p] =
∞
j=0
β
j u( p t+ j ) =
∞
j=0
β
j log( p t+ j ) ,
(11.7)
where we replaced the utility u by the logarithm in the second equality. (11.6)
describes the dynamics of the system and (11.7) is the objective functional that
we seek to maximize. It depends on the time series of profits, which in turn, depend
on the control parameter, the investment i t . The question to answer is now: which
sequence of investments i t maximizes V t [ p]? Thus, what is the best policy or control
law to split the output y t = p t + i t into investment i t and profit p t ? If we pull out
too much profit to enjoy, we will have less capital in the future, such that there will
be less profit to enjoy in the future. Conversely, re-investing too much, leaves too
little profit to enjoy, despite having a huge capital base. Obviously there should be
an optimum investment policy.
Let us now try to find this optimum policy by splitting the objective functional
into the most recent term and the rest. Using p t = λ f (k t ) + (1 − δ)k t − k t+1 , we
can write
V t [ p] =
∞
j=0
β
j u( p t+ j ) = u( p t ) +
∞
j=1
β
j u( p t+ j ) = u( p t ) + β
∞
i=0
β
i u( p t+1+i )
= u( p t ) + βV t+1 [ p] ,
(11.8)
where we first split the sum into terms with j = 0 and j ≥ 1 and then introduce the
new variable i = j − 1, which allows us to rewrite the second term as βV t+1 [ p].
This equation is called Bellman equation. It recursively expresses the objective
functional V t [ p] at time t through the utility that is closest in time u( p t ) and the
objective functional V t+1 [ p] that encodes our minimization objective for the future,
starting at t + 1.
This recursive description of the objective functional V t [ p] gives us a handle to
find the optimum policy. If we assume that we already had found the optimum policy
for V t+1 [ p], let us call it V
∗
t+1 [ p], all we have to do in order to find the optimum
for V t [ p], is to minimize the additional term u( p t ). This algorithm, which forms
the basis of dynamic programming [3], requires, however, to start from the distant
future and work ourselves back towards the point closest in time. The difficulties
of the infinite time horizon (the sum extends to infinity) notwithstanding, we will