

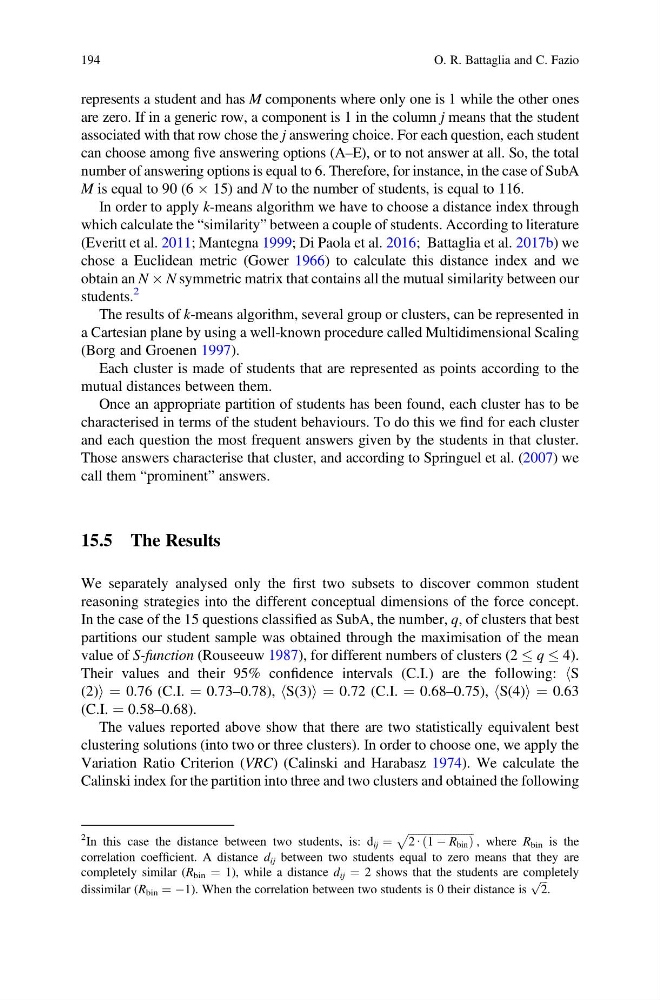
represents a student and has M components where only one is 1 while the other ones
are zero. If in a generic row, a component is 1 in the column j means that the student
associated with that row chose the j answering choice. For each question, each student
can choose among five answering options (A–E), or to not answer at all. So, the total
number of answering options is equal to 6. Therefore, for instance, in the case of SubA
M is equal to 90 (6 Â 15) and N to the number of students, is equal to 116.
In order to apply k-means algorithm we have to choose a distance index through
which calculate the “similarity” between a couple of students. According to literature
(Everitt et al. 2011; Mantegna 1999; Di Paola et al. 2016; Battaglia et al. 2017b) we
chose a Euclidean metric (Gower 1966) to calculate this distance index and we
obtain an N Â N symmetric matrix that contains all the mutual similarity between our
students.
2
The results of k-means algorithm, several group or clusters, can be represented in
a Cartesian plane by using a well-known procedure called Multidimensional Scaling
(Borg and Groenen 1997).
Each cluster is made of students that are represented as points according to the
mutual distances between them.
Once an appropriate partition of students has been found, each cluster has to be
characterised in terms of the student behaviours. To do this we find for each cluster
and each question the most frequent answers given by the students in that cluster.
Those answers characterise that cluster, and according to Springuel et al. (2007) we
call them “prominent” answers.
15.5 The Results
We separately analysed only the first two subsets to discover common student
reasoning strategies into the different conceptual dimensions of the force concept.
In the case of the 15 questions classified as SubA, the number, q, of clusters that best
partitions our student sample was obtained through the maximisation of the mean
value of S-function (Rouseeuw 1987), for different numbers of clusters (2 q 4).
Their values and their 95% confidence intervals (C.I.) are the following: hS
(2)i ¼ 0.76 (C.I. ¼ 0.73–0.78), hS(3)i ¼ 0.72 (C.I. ¼ 0.68–0.75), hS(4)i ¼ 0.63
(C.I. ¼ 0.58–0.68).
The values reported above show that there are two statistically equivalent best
clustering solutions (into two or three clusters). In order to choose one, we apply the
Variation Ratio Criterion (VRC) (Calinski and Harabasz 1974). We calculate the
Calinski index for the partition into three and two clusters and obtained the following
2 In this case the distance between two students, is: d ij ¼
ffiffiffiffiffiffiffiffiffiffiffiffiffiffiffiffiffiffiffiffiffiffiffiffiffi
2 ∙ 1 À R bin
ð
Þ
p
, where R bin is the
correlation coefficient. A distance d ij between two students equal to zero means that they are
completely similar (R bin ¼ 1), while a distance d ij ¼ 2 shows that the students are completely
dissimilar (R bin ¼ À1). When the correlation between two students is 0 their distance is
ffiffi ffi
2
p
.
194
O. R. Battaglia and C. Fazio