

6
1 Forewords: Machine Learning and Physics
is not known. The following example illustrates that even in such cases, it is still
very important to consider a concept similar to entropy.
Relative entropy and Sanov’s theorem
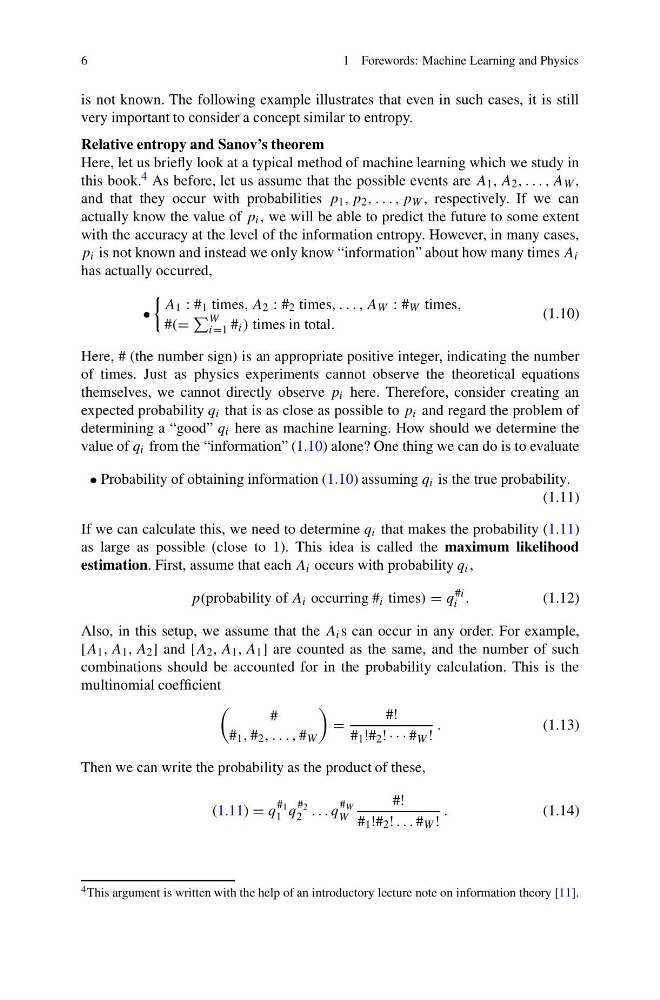
Here, let us briefly look at a typical method of machine learning which we study in
this book. 4 As before, let us assume that the possible events are A 1 , A 2 , . . . , A W ,
and that they occur with probabilities p 1 , p 2 , . . . , p W , respectively. If we can
actually know the value of p i , we will be able to predict the future to some extent
with the accuracy at the level of the information entropy. However, in many cases,
p i is not known and instead we only know “information” about how many times A i
has actually occurred,
•
A 1 : # 1 times, A 2 : # 2 times, . . . , A W : # W times,
#(=
W
i=1 # i ) times in total.
(1.10)
Here, # (the number sign) is an appropriate positive integer, indicating the number
of times. Just as physics experiments cannot observe the theoretical equations
themselves, we cannot directly observe p i here. Therefore, consider creating an
expected probability q i that is as close as possible to p i and regard the problem of
determining a “good” q i here as machine learning. How should we determine the
value of q i from the “information” (1.10) alone? One thing we can do is to evaluate
• Probability of obtaining information (1.10) assuming q i is the true probability.
(1.11)
If we can calculate this, we need to determine q i that makes the probability (1.11)
as large as possible (close to 1). This idea is called the maximum likelihood
estimation. First, assume that each A i occurs with probability q i ,
p(probability of A i occurring # i times) = q
#i
i .
(1.12)
Also, in this setup, we assume that the A i s can occur in any order. For example,
[A 1 , A 1 , A 2 ] and [A 2 , A 1 , A 1 ] are counted as the same, and the number of such
combinations should be accounted for in the probability calculation. This is the
multinomial coefficient
#
# 1 , # 2 , . . . , # W
=
#!
# 1 !# 2 ! · · · # W !
.
(1.13)
Then we can write the probability as the product of these,
(1.11) = q
# 1
1 q
# 2
2 . . . q
# W
W
#!
# 1 !# 2 ! . . . # W !
.
(1.14)
4 This argument is written with the help of an introductory lecture note on information theory [11].