

86
L. Fang and S. Li
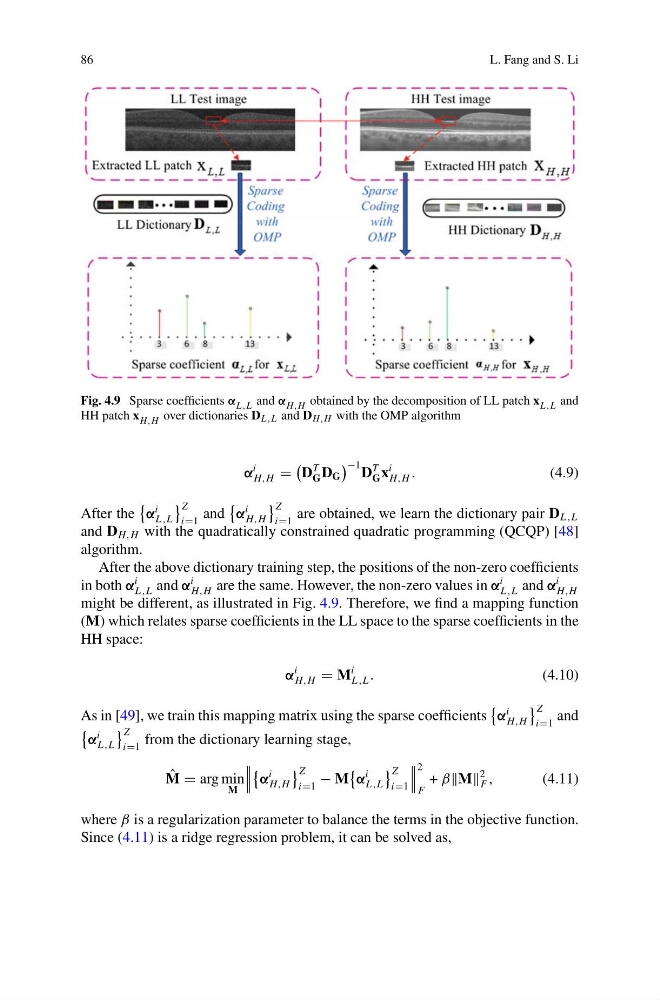
Fig. 4.9 Sparse coefficients α L ,L and α H,H obtained by the decomposition of LL patch x L ,L and
HH patch x H,H over dictionaries D L ,L and D H,H with the OMP algorithm
α
i
H,H
D
T
G D G
−1 D
T
G x
i
H,H .
(4.9)
After the
α
i
L ,L
Z
i1
and
α
i
H,H
Z
i1
are obtained, we learn the dictionary pair D L ,L
and D H,H with the quadratically constrained quadratic programming (QCQP) [48]
algorithm.
After the above dictionary training step, the positions of the non-zero coefficients
in both α
i
L ,L and α
i
H,H are the same. However, the non-zero values in α
i
L ,L and α
i
H,H
might be different, as illustrated in Fig. 4.9. Therefore, we find a mapping function
(M) which relates sparse coefficients in the LL space to the sparse coefficients in the
HH space:
α
i
H,H M
i
L ,L .
(4.10)
As in [49], we train this mapping matrix using the sparse coefficients
α
i
H,H
Z
i1
and
α
i
L ,L
Z
i1
from the dictionary learning stage,
ˆ
M arg min
M
α
i
H,H
Z
i1
− M
α
i
L ,L
Z
i1
2
F
+ βM
2
F ,
(4.11)
where β is a regularization parameter to balance the terms in the objective function.
Since (4.11) is a ridge regression problem, it can be solved as,