

Online optimization algorithms 193
7.3 ALGORITHMS FOR ONLINE OPTIMIZATION
An algorithm that is efficient for smooth functions may be unsuitable for online
applications if it is sensitive to noise. In this section we first perform tests for
some of the algorithms by adding noise to analytic objective functions.
Modifications of two of the popular derivative-free algorithms are described. The robust conjugate direction search (RCDS) method [57] is modified
from Powell’s method by replacing its 1-dimensional optimizer with a robust
optimizer that is aware of the noise level in the functions. The robust simplex
(RSimplex) [55] is a modification of the Nelder-Mead simplex method. With
the modifications, the algorithms become more tolerant of noise.
7.3.1 Testing of traditional algorithms
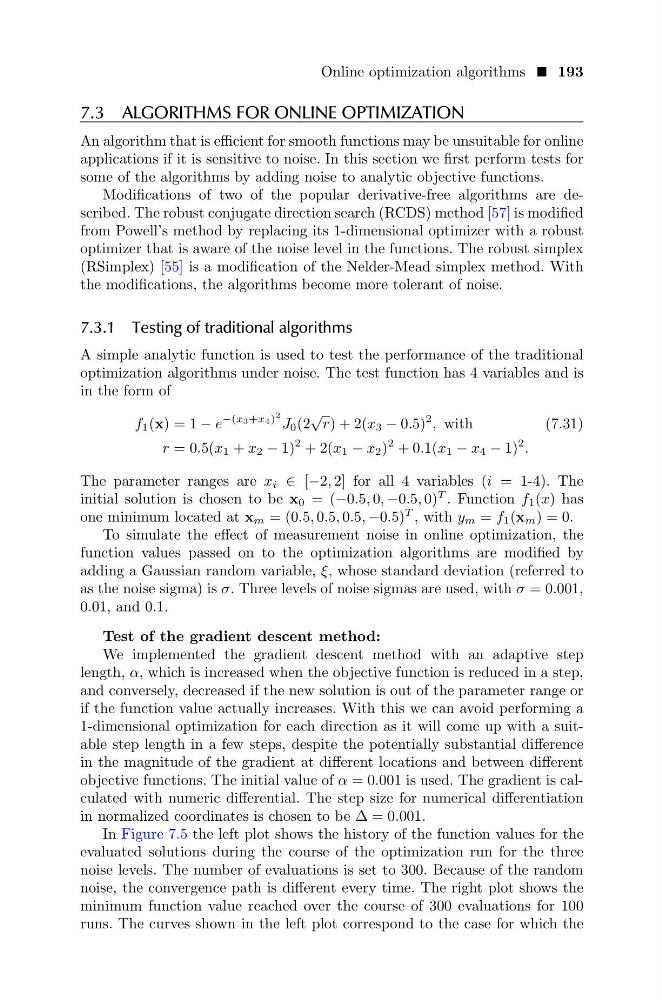
A simple analytic function is used to test the performance of the traditional
optimization algorithms under noise. The test function has 4 variables and is
in the form of
f 1 (x) = 1 − e
−(x3+x4)
2 J 0 (2
√
r) + 2(x 3 − 0.5)
2 , with
(7.31)
r = 0.5(x 1 + x 2 − 1)
2 + 2(x 1 − x 2 )
2 + 0.1(x 1 − x 4 − 1)
2 .
The parameter ranges are x i ∈ [−2, 2] for all 4 variables (i = 1-4). The
initial solution is chosen to be x 0 = (−0.5, 0, −0.5, 0)
T . Function f 1 (x) has
one minimum located at x m = (0.5, 0.5, 0.5, −0.5)
T , with y m = f 1 (x m ) = 0.
To simulate the effect of measurement noise in online optimization, the
function values passed on to the optimization algorithms are modified by
adding a Gaussian random variable, ξ, whose standard deviation (referred to
as the noise sigma) is σ. Three levels of noise sigmas are used, with σ = 0.001,
0.01, and 0.1.
Test of the gradient descent method:
We implemented the gradient descent method with an adaptive step
length, α, which is increased when the objective function is reduced in a step,
and conversely, decreased if the new solution is out of the parameter range or
if the function value actually increases. With this we can avoid performing a
1-dimensional optimization for each direction as it will come up with a suitable step length in a few steps, despite the potentially substantial difference
in the magnitude of the gradient at different locations and between different
objective functions. The initial value of α = 0.001 is used. The gradient is calculated with numeric differential. The step size for numerical differentiation
in normalized coordinates is chosen to be ∆ = 0.001.
In Figure 7.5 the left plot shows the history of the function values for the
evaluated solutions during the course of the optimization run for the three
noise levels. The number of evaluations is set to 300. Because of the random
noise, the convergence path is different every time. The right plot shows the
minimum function value reached over the course of 300 evaluations for 100
runs. The curves shown in the left plot correspond to the case for which the