

469
where d is the number of input variables, x i represents the input variables, β are the weights
which connect the input nodes to the hidden nodes, v represents the hidden layer linear combiner, ϕ is the activation function used in the hidden layer and z represents the hidden node
value. The weight with zero index is the bias element which is related to x 0 = 1. The reader
should refer to Izenman (2008) for more details.
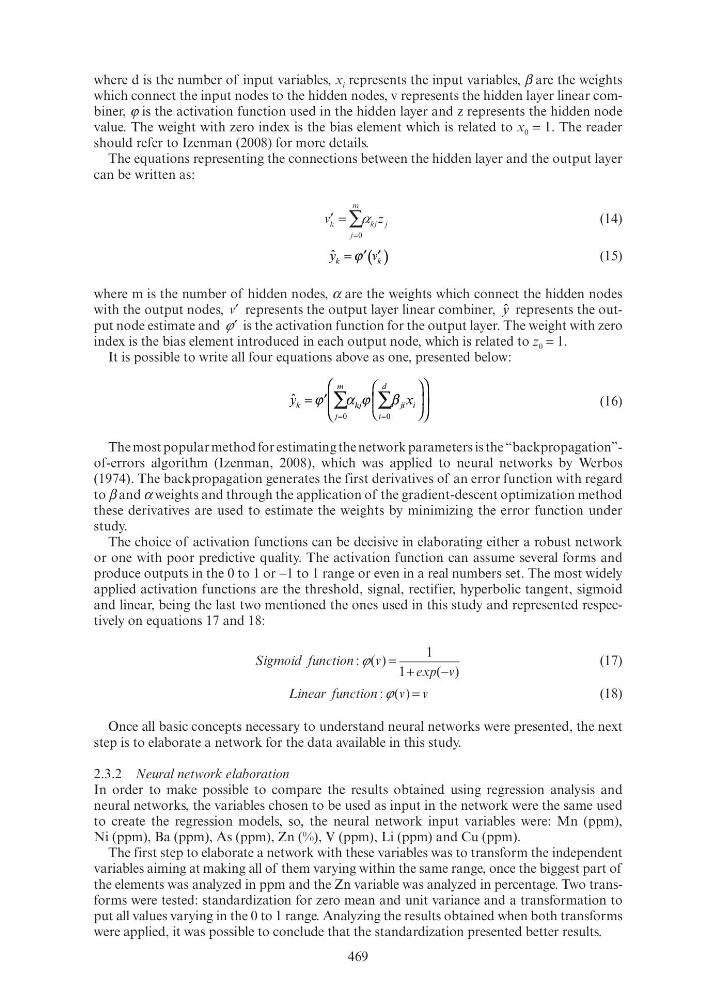
The equations representing the connections between the hidden layer and the output layer
can be written as:
′
=
∑
v
z
= ∑
k
j
m
kj j
0
α
∑ ∑ ∑ k
(14)
( )
ˆ k
k
(
y
v
(
k
(
ϕ ′ ′
(15)
where m is the number of hidden nodes, α are the weights which connect the hidden nodes
with the output nodes, ′
v represents the output layer linear combiner, ˆ
y represents the output node estimate and ′
ϕ′ is the activation function for the output layer. The weight with zero
index is the bias element introduced in each output node, which is related to z 0 = 1.
It is possible to write all four equations above as one, presented below:
ˆ k
y k ϕ
⎛
⎞
m
⎞ ⎞
d
′
⎟
⎛
⎞
⎛
⎞
⎞ ⎞
β
⎞ ⎞
β
⎞ ⎞ ⎞
β
⎟
⎟ ⎟
⎟
i
ji j i
x
ji
β j i
ji j
⎟ ⎟
i
ji j
⎝
⎠
0
j 0 0
⎜
⎟
⎜
⎟
kj ⎝
⎠
0
i
ji i
ji j j
⎛ ⎛
β β β
kj kj
α ϕ
kj kj
β
kj kj kj
(16)
The most popular method for estimating the network parameters is the “backpropagation”of-errors algorithm (Izenman, 2008), which was applied to neural networks by Werbos
(1974). The backpropagation generates the first derivatives of an error function with regard
to β and α weights and through the application of the gradient-descent optimization method
these derivatives are used to estimate the weights by minimizing the error function under
study.
The choice of activation functions can be decisive in elaborating either a robust network
or one with poor predictive quality. The activation function can assume several forms and
produce outputs in the 0 to 1 or −1 to 1 range or even in a real numbers set. The most widely
applied activation functions are the threshold, signal, rectifier, hyperbolic tangent, sigmoid
and linear, being the last two mentioned the ones used in this study and represented respectively on equations 17 and 18:
Sigmoi i
d f
i i unction
f f
v
exp x
: ( )
( )
v
ϕ ( = + exp x (
1
1
(17)
Linear i i
function
v v
: ( )
ϕ (
(18)
Once all basic concepts necessary to understand neural networks were presented, the next
step is to elaborate a network for the data available in this study.
2.3.2 Neural network elaboration
In order to make possible to compare the results obtained using regression analysis and
neural networks, the variables chosen to be used as input in the network were the same used
to create the regression models, so, the neural network input variables were: Mn (ppm),
Ni (ppm), Ba (ppm), As (ppm), Zn (%), V (ppm), Li (ppm) and Cu (ppm).
The first step to elaborate a network with these variables was to transform the independent
variables aiming at making all of them varying within the same range, once the biggest part of
the elements was analyzed in ppm and the Zn variable was analyzed in percentage. Two transforms were tested: standardization for zero mean and unit variance and a transformation to
put all values varying in the 0 to 1 range. Analyzing the results obtained when both transforms
were applied, it was possible to conclude that the standardization presented better results.