

95
second is the contacts between several ore units in the Dales Gorge Member at a typical
Brockman style deposit. The first case contains a soft to hard contact that has been successfully automatically identified using Gaussian Processes on APR signatures (Silversides &
Melkumyan 2018). However, the second test contains much more subtle changes between the
units and the same technique was not successful in classifying these units.
2 BACKGROUND
In this paper two different approaches using Gaussian Processes (GPs) are presented.
A Gaussian Process is defined mathematically as an infinite collection of random variables,
any finite number of which has a joint Gaussian distribution (Bishop 2006; Rasmussen &
Williams 2006). This is a probabilistic method of modelling functions that represent quantities of interest within a data set. Applying GPs involves two steps: training and inference.
GPs are trained by optimising the hyperparameters that are defined by a given covariance
function. This covariance function partially describes the general characteristics of the relationship between the inputs and outputs, such as the level of smoothness. This study uses the
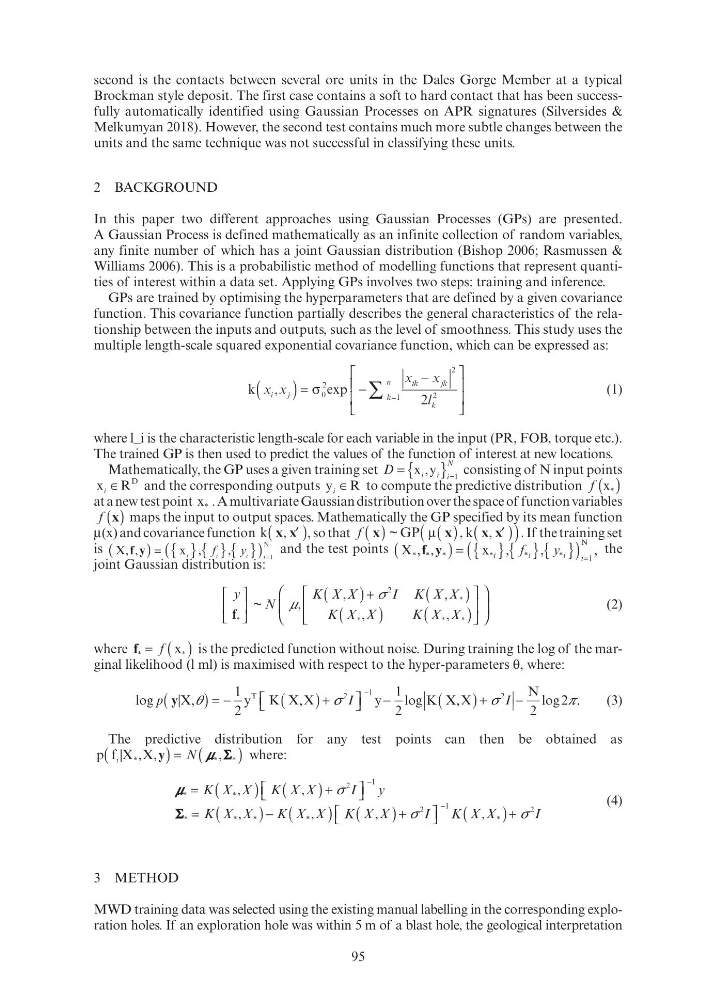
multiple length-scale squared exponential covariance function, which can be expressed as:
k
e xp
x x
l
i
j
ik
jk
k
l
k
n
( )
−
exp
⎡
⎣
⎢
⎡ ⎡
⎢
⎣ ⎣
⎢ ⎢
⎤
⎦
⎥
⎤ ⎤
⎥
⎦ ⎦
⎥ ⎥
=
∑
σ 0
2
2
2
1
2
(1)
where l_i is the characteristic length-scale for each variable in the input (PR, FOB, torque etc.).
The trained GP is then used to predict the values of the function of interest at new locations.
Mathematically, the GP uses a given training set D
i
N
= { }
i
i =
i
1
consisting of N input points
x R
D
i
and the corresponding outputs y R
i
to compute the predictive distribution f ( )
x *
at a new test point x * . A multivariate Gaussian distribution over the space of function variables
f ( )
x maps the input to output spaces. Mathematically the GP specified by its mean function
μ(x) and covariance function k(
)
x, ′ ′ ′ , so that f ( )
x
( )
x
(
)
x x′
x x
(
)
,
( )
x
(
.
)
x )
GP
k
μ
If the training set
is
N
(
)
X,f y
,
(
)
,
{ }
x { } { } =
,
} {
i
,
} {
1
and the test points
N ,
(
)
X *
*
,f y
,
*
(
)
)
{ }
x *
x { } { }
*
=
,
} {
i
,
}
*
{
* *
1
the
joint Gaussian distribution is:
y
N
K
I K
K
K
f *
f f
K
⎡
⎣
⎢
⎡ ⎡
⎣ ⎣
⎤
⎦
⎥
⎤ ⎤
⎦ ⎦
(
)
X X
(
)
X X *
X X
(
)
X X
*
X X X
(
)
X X
X X *
X X
⎡
⎣
⎢
⎡ ⎡
⎣ ⎣
⎤
⎦
⎥
⎤ ⎤
⎦ ⎦
⎛
⎝
⎜
⎛ ⎛
⎝ ⎝
⎞
⎠
⎟
⎞ ⎞
⎠ ⎠
~
,
N
⎝
⎜
⎝ ⎝
I K
)
X
( X
K
)
X
( *
X X
μ,
2
(2)
where f *
f f = ( )
f
is the predicted function without noise. During training the log of the marginal likelihood (l ml) is maximised with respect to the hyper-parameters θ, where:
log
l
log
p
I
y
K
log
N
T
K
T
(
)
,
|X θ
(
)
,
(
)
,
X,
⎡ ⎣
⎤ ⎦
(
)
,
X,
−
1
2
1
2
2
g (
)
,
2
2
1
2
π . .
(3)
The predictive distribution for any test points can then be obtained as
p
N
(
)
f |X X
* X
i
f
, ,
X y = (
)
*
*
,
* * * * * *
where:
μ μ
μ μ *
μ μ
μ μ μ μ
*
= (
)
*
(
)+
⎡ ⎣
⎤ ⎦
= (
)
*
(
) (
)
⎡ ⎣ ⎡ ⎡
−
K ( *
K
) ⎡ ⎡ ⎡
I
y
⎤ ⎦ ⎤ ⎤
K ( *
K
)
* −
*
K (
I
) +
) (
⎣ ⎡ ⎡ K
) ⎡ ⎡
)
*
( *
*
*
σ
σ
2
σ σ
1
2
Σ Σ
Σ Σ
⎤ ⎤ ⎦ ⎤ ⎤ ⎤ ⎤
(
)
−1
2
K (
I
) +
2
σ
2 2
(4)
3 METHOD
MWD training data was selected using the existing manual labelling in the corresponding exploration holes. If an exploration hole was within 5 m of a blast hole, the geological interpretation