

198
F. Nielsen and K. Sun
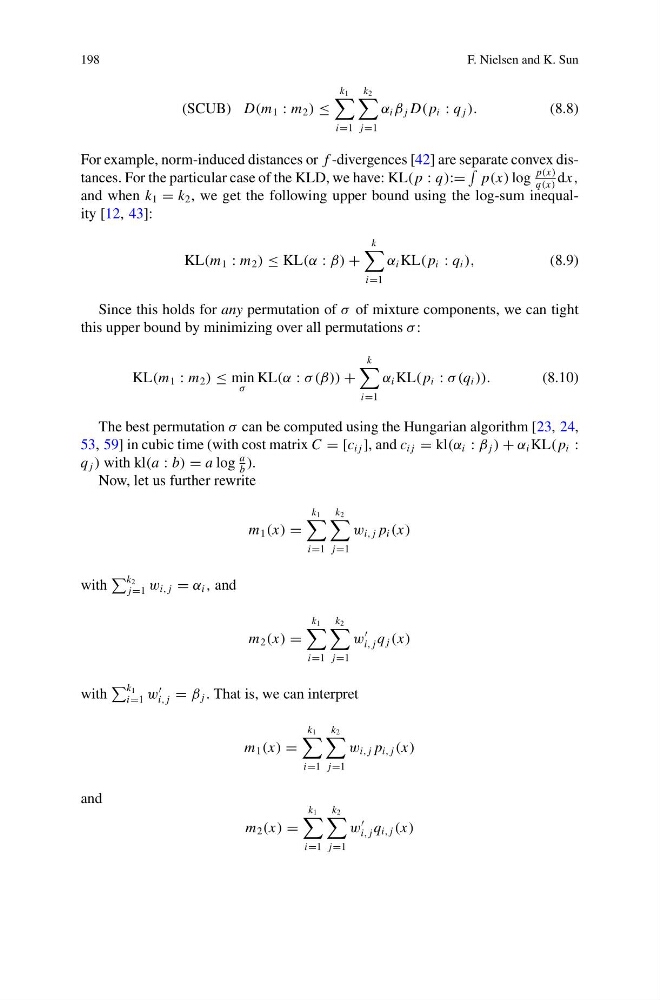
(SCUB) D(m 1 : m 2 ) ≤
k 1
i=1
k 2
j=1
α i β j D( p i : q j ).
(8.8)
For example, norm-induced distances or f -divergences [42] are separate convex distances. For the particular case of the KLD, we have: KL( p : q):=
p(x) log
p(x)
q(x)
dx,
and when k 1 = k 2 , we get the following upper bound using the log-sum inequality [12, 43]:
KL(m 1 : m 2 ) ≤ KL(α : β) +
k
i=1
α i KL( p i : q i ),
(8.9)
Since this holds for any permutation of σ of mixture components, we can tight
this upper bound by minimizing over all permutations σ :
KL(m 1 : m 2 ) ≤ min
σ
KL(α : σ (β)) +
k
i=1
α i KL( p i : σ (q i )).
(8.10)
The best permutation σ can be computed using the Hungarian algorithm [23, 24,
53, 59] in cubic time (with cost matrix C = [c i j ], and c i j = kl(α i : β j ) + α i KL( p i :
q j ) with kl(a : b) = a log
a
b
).
Now, let us further rewrite
m 1 (x) =
k 1
i=1
k 2
j=1
w i, j p i (x)
with
k 2
j=1 w i, j = α i , and
m 2 (x) =
k 1
i=1
k 2
j=1
w
i, j q j (x)
with
k 1
i=1 w
i, j = β j . That is, we can interpret
m 1 (x) =
k 1
i=1
k 2
j=1
w i, j p i, j (x)
and
m 2 (x) =
k 1
i=1
k 2
j=1
w
i, j q i, j (x)