

The core component of the BP algorithm is the backpropagation algorithm. The BP
algorithm is based on a stochastic gradient descent strategy and adjusts the parameters
according to the negative direction of the gradient of the error [13]. The derivative of
layer between hidden layer and output layer matrix is shown as (1)
Dw hj ¼ Àg
@E k
@w hj
ð1Þ
By observing Formula (1), it can be found that the input value corresponding to the
j output neuron is affected ^ y
k
j first and then responding to its output value E k , and finally
affecting the error, according to the chain derivation rule [14]:
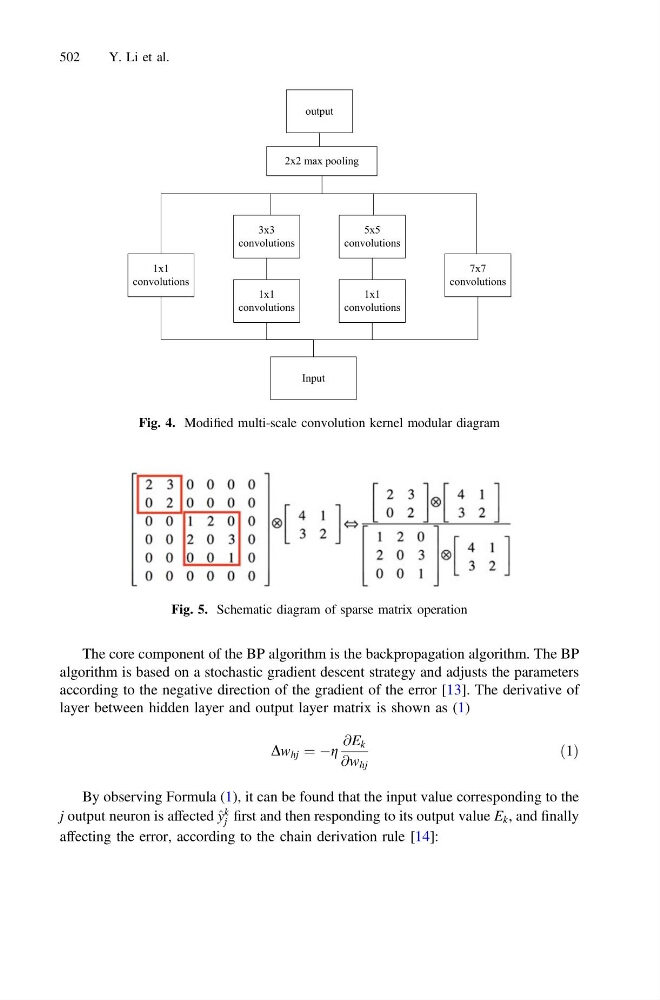
1x1
convolutions
Input
1x1
convolutions
1x1
convolutions
7x7
convolutions
3x3
convolutions
5x5
convolutions
2x2 max pooling
output
Fig. 4. Modified multi-scale convolution kernel modular diagram
Fig. 5. Schematic diagram of sparse matrix operation
502
Y. Li et al.