

Zone-Based Resource Allocation Strategy for Heterogeneous . . .
119
Table 5. Hardware configuration of
Experiment II
zone no character
computers no
1
Worker
1
2
Worker
2, 3, 4
3
Worker driver 5, 6, 7, 8
Table 6. Configuration of Experiment II
test no Native Spark
required cores
Spark with ZbRAS
job propriety
1
12 cores
2
2
8 cores
2
3
8 cores
3
4
16 cores
1
Table 7. Result of Test 1
Native
Spark
ZbRAS Optimization
rate
Time 33.41 s
28.01 s 16.2%
Node 4, 5, 6,
7, 8
2, 3, 4
Table 8. Result of Test 2
Native
Spark
ZbRAS Optimization
rate
Time 46.69 s
37.11 s 20.5%
Node 4, 5, 6, 7 2, 3
After Experiment I to carry out zone division, Experiment II can be carried
out on zone scheduling to test the degree of optimization of zone scheduling to
Spark. Experiment II will use zone scheduling and native Spark scheduling to test
and compare the scheduling results and running time of the two. The purpose
of zone scheduling is to select the optimal computing resources for high-priority
jobs when the computing resources in the cluster are sufficient.
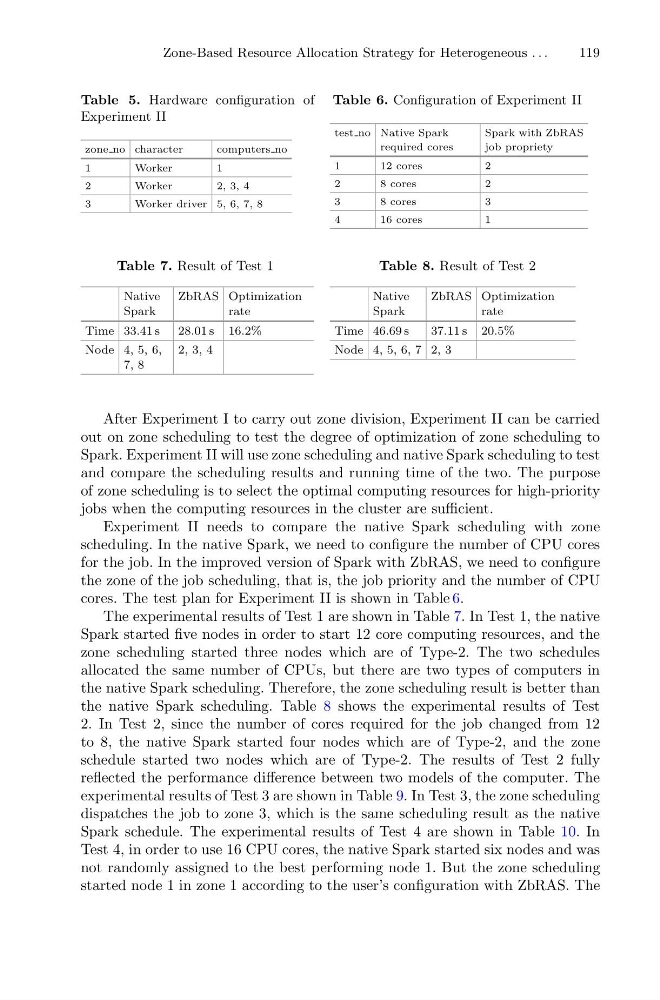
Experiment II needs to compare the native Spark scheduling with zone
scheduling. In the native Spark, we need to configure the number of CPU cores
for the job. In the improved version of Spark with ZbRAS, we need to configure
the zone of the job scheduling, that is, the job priority and the number of CPU
cores. The test plan for Experiment II is shown in Table 6.
The experimental results of Test 1 are shown in Table 7. In Test 1, the native
Spark started five nodes in order to start 12 core computing resources, and the
zone scheduling started three nodes which are of Type-2. The two schedules
allocated the same number of CPUs, but there are two types of computers in
the native Spark scheduling. Therefore, the zone scheduling result is better than
the native Spark scheduling. Table 8 shows the experimental results of Test
2. In Test 2, since the number of cores required for the job changed from 12
to 8, the native Spark started four nodes which are of Type-2, and the zone
schedule started two nodes which are of Type-2. The results of Test 2 fully
reflected the performance difference between two models of the computer. The
experimental results of Test 3 are shown in Table 9. In Test 3, the zone scheduling
dispatches the job to zone 3, which is the same scheduling result as the native
Spark schedule. The experimental results of Test 4 are shown in Table 10. In
Test 4, in order to use 16 CPU cores, the native Spark started six nodes and was
not randomly assigned to the best performing node 1. But the zone scheduling
started node 1 in zone 1 according to the user’s configuration with ZbRAS. The