

Zone-Based Resource Allocation Strategy for Heterogeneous . . .
117
The following describes the zone-based resource allocation strategy in the
form of pseudocode, see Algorithm 1. The resource allocation strategy relies on
two input parameters, the configuration item cores.max represents the number
of cores that the user wants to start for the job, and the configuration item
zone.level represents the target area that the user wants to schedule for the job,
which reflects the priority score of the job.
Spark processes on different nodes communicate through remote procedure
calls [5] (RPC). In order to keep the functionality and structure of Spark intact,
and to ensure the elegance and clarity of the code, we chose to set up a new component, the Schedule Center. The Schedule Center is responsible for scheduling
optimization functions and providing services to Spark.
3 Simulation
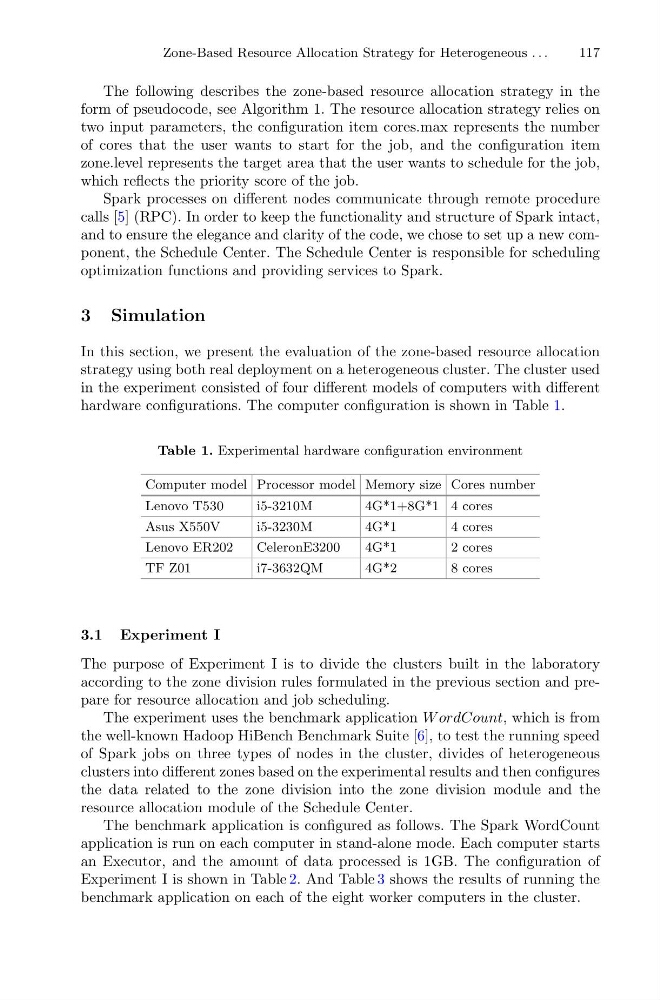
In this section, we present the evaluation of the zone-based resource allocation
strategy using both real deployment on a heterogeneous cluster. The cluster used
in the experiment consisted of four different models of computers with different
hardware configurations. The computer configuration is shown in Table 1.
Table 1. Experimental hardware configuration environment
Computer model Processor model Memory size Cores number
Lenovo T530
i5-3210M
4G*1+8G*1 4 cores
Asus X550V
i5-3230M
4G*1
4 cores
Lenovo ER202
CeleronE3200
4G*1
2 cores
TF Z01
i7-3632QM
4G*2
8 cores
3.1 Experiment I
The purpose of Experiment I is to divide the clusters built in the laboratory
according to the zone division rules formulated in the previous section and prepare for resource allocation and job scheduling.
The experiment uses the benchmark application W ordCount, which is from
the well-known Hadoop HiBench Benchmark Suite [6], to test the running speed
of Spark jobs on three types of nodes in the cluster, divides of heterogeneous
clusters into different zones based on the experimental results and then configures
the data related to the zone division into the zone division module and the
resource allocation module of the Schedule Center.
The benchmark application is configured as follows. The Spark WordCount
application is run on each computer in stand-alone mode. Each computer starts
an Executor, and the amount of data processed is 1GB. The configuration of
Experiment I is shown in Table 2. And Table 3 shows the results of running the
benchmark application on each of the eight worker computers in the cluster.