

5 Machine Learning for IoT
303
X 1
X 2
X n
b
W
1
W
2
W
n
…
…
Sum
Sum
Sum
z
1
z
1
z
1
argmax
Softmax
Output
Weights
Inputs
Cross entropy
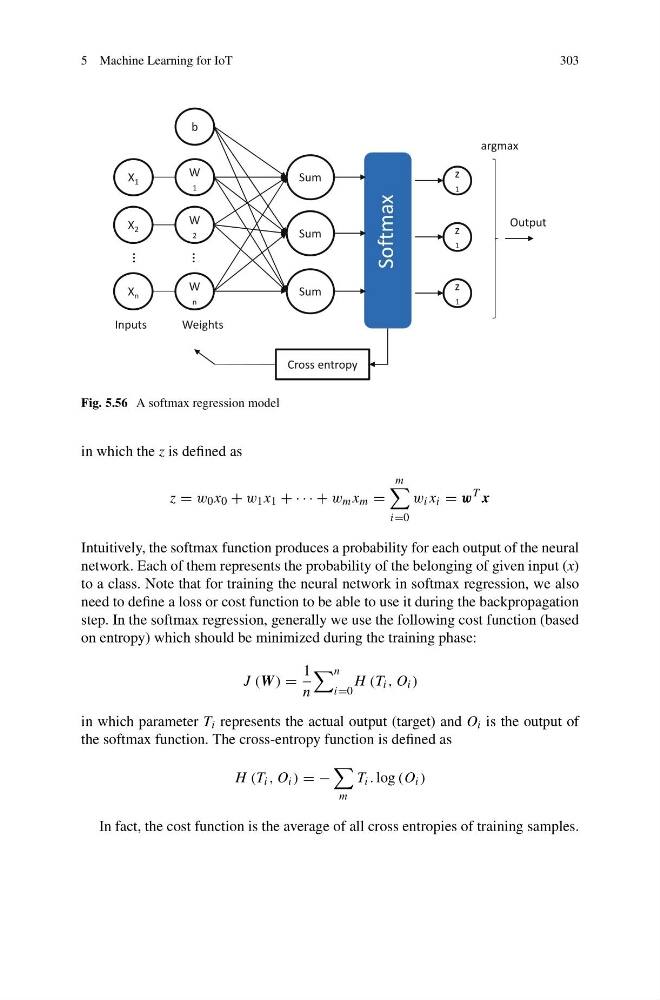
Fig. 5.56 A softmax regression model
in which the z is defined as
z = w 0 x 0 + w 1 x 1 + · · · + w m x m =
m
i=0
w i x i = w
T x
Intuitively, the softmax function produces a probability for each output of the neural
network. Each of them represents the probability of the belonging of given input (x)
to a class. Note that for training the neural network in softmax regression, we also
need to define a loss or cost function to be able to use it during the backpropagation
step. In the softmax regression, generally we use the following cost function (based
on entropy) which should be minimized during the training phase:
J (W ) =
1
n
n
i=0
H (T i , O i )
in which parameter T i represents the actual output (target) and O i is the output of
the softmax function. The cross-entropy function is defined as
H (T i , O i ) = −
m
T i . log (O i )
In fact, the cost function is the average of all cross entropies of training samples.