

7 A Review of Feature Reduction Methods …
123
7.2 Feature Selection
Feature selection works by selecting a subset of features from the original feature set
and removing irrelevant features without altering the original representation of the
data, on the basis of certain relevance criteria [18, 26–28]. The physical meanings
of the features are retained.
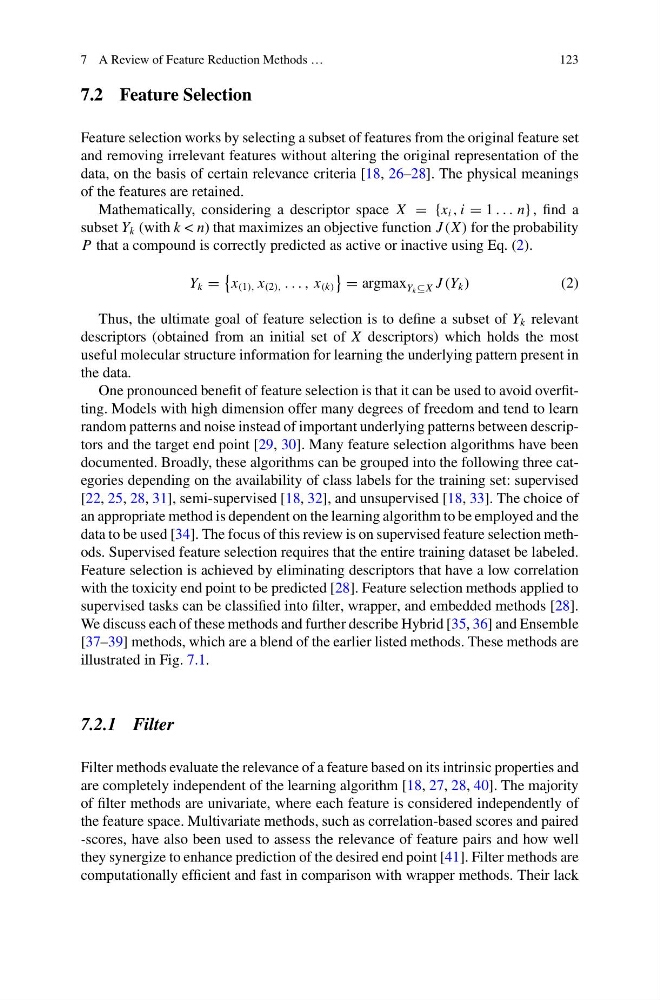
Mathematically, considering a descriptor space X = {x i , i = 1 . . . n} , find a
subset Y k (with k < n) that maximizes an objective function J (X ) for the probability
P that a compound is correctly predicted as active or inactive using Eq. (2).
Y k =
x (1), x (2), . . . , x (k)
= argmax Y k ⊆X J (Y k )
(2)
Thus, the ultimate goal of feature selection is to define a subset of Y k relevant
descriptors (obtained from an initial set of X descriptors) which holds the most
useful molecular structure information for learning the underlying pattern present in
the data.
One pronounced benefit of feature selection is that it can be used to avoid overfitting. Models with high dimension offer many degrees of freedom and tend to learn
random patterns and noise instead of important underlying patterns between descriptors and the target end point [29, 30]. Many feature selection algorithms have been
documented. Broadly, these algorithms can be grouped into the following three categories depending on the availability of class labels for the training set: supervised
[22, 25, 28, 31], semi-supervised [18, 32], and unsupervised [18, 33]. The choice of
an appropriate method is dependent on the learning algorithm to be employed and the
data to be used [34]. The focus of this review is on supervised feature selection methods. Supervised feature selection requires that the entire training dataset be labeled.
Feature selection is achieved by eliminating descriptors that have a low correlation
with the toxicity end point to be predicted [28]. Feature selection methods applied to
supervised tasks can be classified into filter, wrapper, and embedded methods [28].
We discuss each of these methods and further describe Hybrid [35, 36] and Ensemble
[37–39] methods, which are a blend of the earlier listed methods. These methods are
illustrated in Fig. 7.1.
7.2.1 Filter
Filter methods evaluate the relevance of a feature based on its intrinsic properties and
are completely independent of the learning algorithm [18, 27, 28, 40]. The majority
of filter methods are univariate, where each feature is considered independently of
the feature space. Multivariate methods, such as correlation-based scores and paired
-scores, have also been used to assess the relevance of feature pairs and how well
they synergize to enhance prediction of the desired end point [41]. Filter methods are
computationally efficient and fast in comparison with wrapper methods. Their lack