

Semantic IoT Interoperability and Data Analytics Using …
257
Table 3 Tokenization of testdata
newDocuments = tokenizedDocument
9 tokens:
reason common cold result fever kid results into chest congestion
bagOfWords with properties
Counts
Vocabulary:
NumWords:
NumDocuments
[13 × 54 double]
[1 × 54 string]
54
13
the reduction in data
0.8704
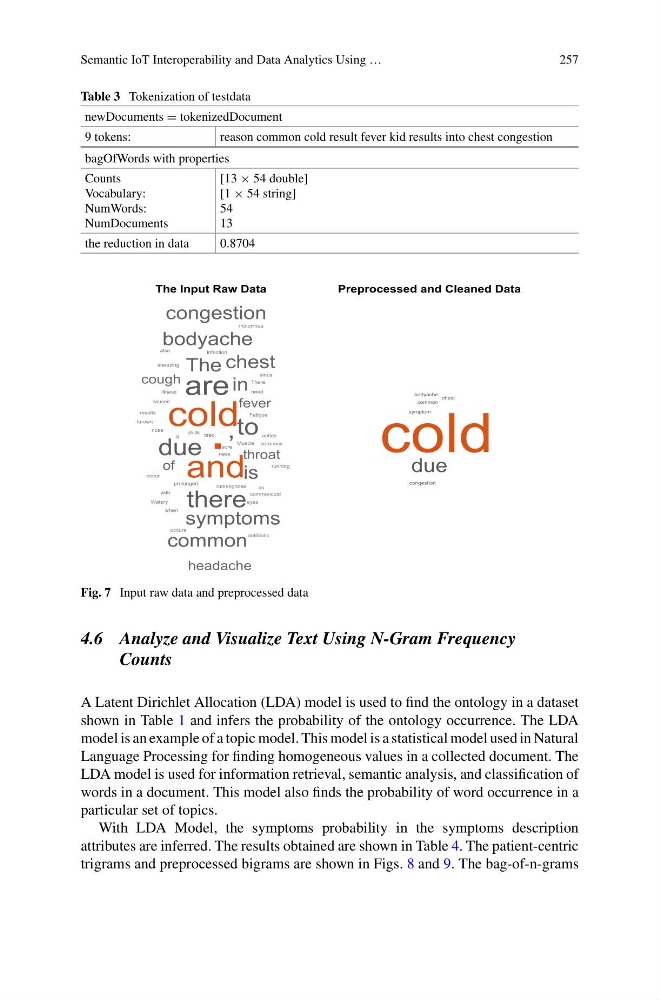
Fig. 7 Input raw data and preprocessed data
4.6 Analyze and Visualize Text Using N-Gram Frequency
Counts
A Latent Dirichlet Allocation (LDA) model is used to find the ontology in a dataset
shown in Table 1 and infers the probability of the ontology occurrence. The LDA
model is an example of a topic model. This model is a statistical model used in Natural
Language Processing for finding homogeneous values in a collected document. The
LDA model is used for information retrieval, semantic analysis, and classification of
words in a document. This model also finds the probability of word occurrence in a
particular set of topics.
With LDA Model, the symptoms probability in the symptoms description
attributes are inferred. The results obtained are shown in Table 4. The patient-centric
trigrams and preprocessed bigrams are shown in Figs. 8 and 9. The bag-of-n-grams