

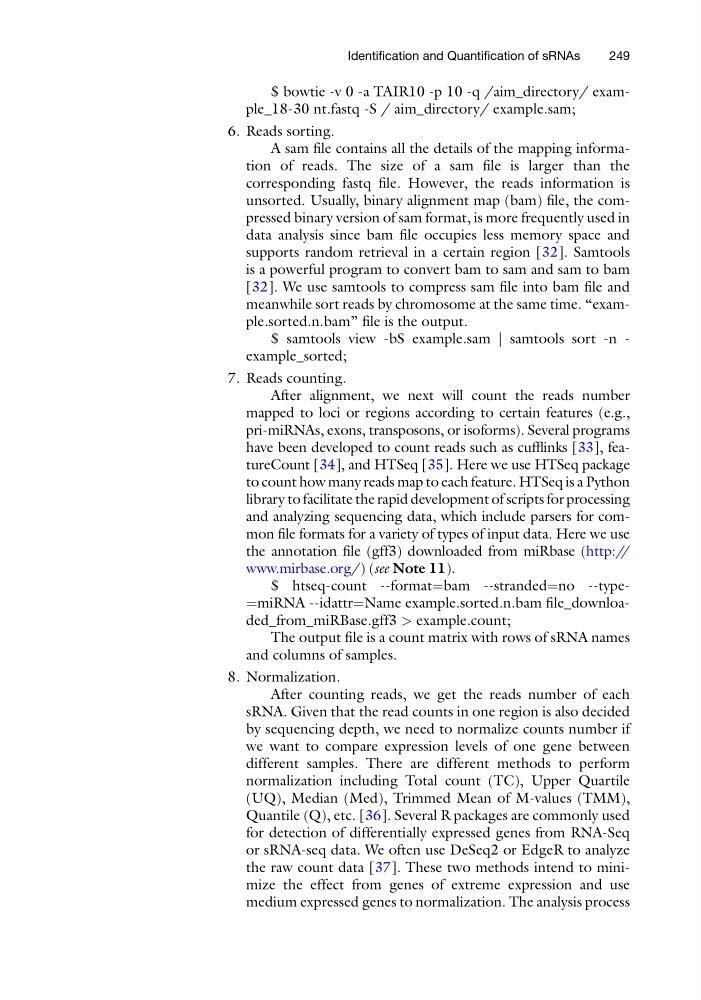
$ bowtie -v 0 -a TAIR10 -p 10 -q /aim_directory/ example_18-30 nt.fastq -S / aim_directory/ example.sam;
6. Reads sorting.
A sam file contains all the details of the mapping information of reads. The size of a sam file is larger than the
corresponding fastq file. However, the reads information is
unsorted. Usually, binary alignment map (bam) file, the compressed binary version of sam format, is more frequently used in
data analysis since bam file occupies less memory space and
supports random retrieval in a certain region [32]. Samtools
is a powerful program to convert bam to sam and sam to bam
[32]. We use samtools to compress sam file into bam file and
meanwhile sort reads by chromosome at the same time. “example.sorted.n.bam” file is the output.
$ samtools view -bS example.sam | samtools sort -n -
example_sorted;
7. Reads counting.
After alignment, we next will count the reads number
mapped to loci or regions according to certain features (e.g.,
pri-miRNAs, exons, transposons, or isoforms). Several programs
have been developed to count reads such as cufflinks [33], featureCount [34], and HTSeq [35]. Here we use HTSeq package
to count how many reads map to each feature. HTSeq is a Python
library to facilitate the rapid development of scripts for processing
and analyzing sequencing data, which include parsers for common file formats for a variety of types of input data. Here we use
the annotation file (gff3) downloaded from miRbase (http://
www.mirbase.org/) (see Note 11).
$ htseq-count --format¼bam --stranded¼no --type¼miRNA --idattr¼Name example.sorted.n.bam file_downloaded_from_miRBase.gff3 > example.count;
The output file is a count matrix with rows of sRNA names
and columns of samples.
8. Normalization.
After counting reads, we get the reads number of each
sRNA. Given that the read counts in one region is also decided
by sequencing depth, we need to normalize counts number if
we want to compare expression levels of one gene between
different samples. There are different methods to perform
normalization including Total count (TC), Upper Quartile
(UQ), Median (Med), Trimmed Mean of M-values (TMM),
Quantile (Q), etc. [36]. Several R packages are commonly used
for detection of differentially expressed genes from RNA-Seq
or sRNA-seq data. We often use DeSeq2 or EdgeR to analyze
the raw count data [37]. These two methods intend to minimize the effect from genes of extreme expression and use
medium expressed genes to normalization. The analysis process
Identification and Quantification of sRNAs
249