

Urban Management: Learning from Green Infrastructure …
497
Ministry of Health. IBGE@Cidades synthesizes information about Brazilian States
and Municipalities, including indicators, research reports, infographics and maps.
These values are mostly based on or derived from the last census survey dating
back to 2010. The number of vehicles is based on the number of licenses issued
each year and includes all types of vehicles such as automobiles, buses, trucks,
tractors, motorcycles, and tricycles. The morbidity data of respiratory diseases (CID10 Chapter X) and circulatory diseases (CID-10 Chapter IX) were extracted from
TabNet—DATASUS, and include both emergency and elective care in 2010 (by
selecting all months).
“ARB”, the percentage of urban households in streets with trees, surveyed in
the 2010 census, was taken as the green infrastructure indicator. GDP was taken
per capita. The rates per 1000 inhabitants were taken for vehicles and morbidity of
respiratory and circulatory diseases.
Variables analysis The variables analysis was performed by calculating descriptive
statistics such as the average, minimum, maximum, variance, standard deviation,
standard error and Pearson’s coefficient of variation, as well as the histogram for
each variable. Moreover, the matrix of linear correlation was calculated and data
mining techniques were performed by multivariate analysis. The multivariate analysis included two clustering methods, as well as the factor and main components
searching.
The hierarchical tree diagram (dendrogram) and k-means were applied for clustering using Euclidian distances. Cluster analysis allows verifying which variables
have the same characteristics, classifying them into different groups.
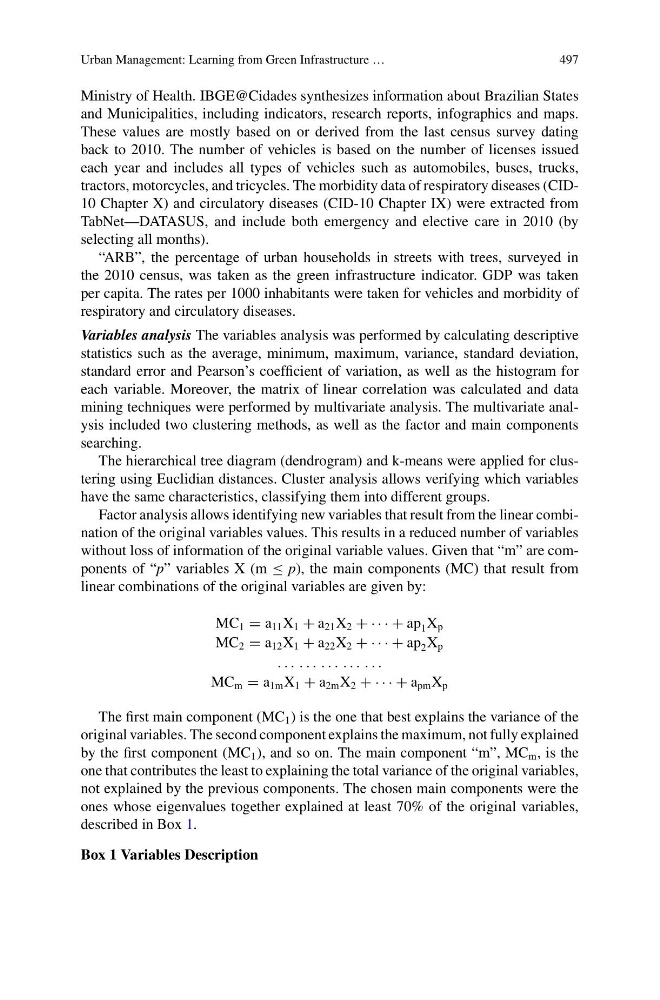
Factor analysis allows identifying new variables that result from the linear combination of the original variables values. This results in a reduced number of variables
without loss of information of the original variable values. Given that “m” are components of “p” variables X (m ≤ p), the main components (MC) that result from
linear combinations of the original variables are given by:
MC 1 = a 11 X 1 + a 21 X 2 + · · · + ap 1 X p
MC 2 = a 12 X 1 + a 22 X 2 + · · · + ap 2 X p
. . . . . . . . . . . . . . .
MC m = a 1m X 1 + a 2m X 2 + · · · + a pm X p
The first main component (MC 1 ) is the one that best explains the variance of the
original variables. The second component explains the maximum, not fully explained
by the first component (MC 1 ), and so on. The main component “m”, MC m , is the
one that contributes the least to explaining the total variance of the original variables,
not explained by the previous components. The chosen main components were the
ones whose eigenvalues together explained at least 70% of the original variables,
described in Box 1.
Box 1 Variables Description