

7 Land-use and Catchment Characteristics
145
similar. In addition, the program produces an output map where each image pixel is
assigned a class label, according to the feature space partitioning.
Some algorithms are able to decide that feature vectors in certain parts of the
feature space are not similar to any of the trained classes. They assign to those image
pixels the class label unknown. In case the area indeed contains classes that were not
included in the training phase, the result unknown may be better than assignemt to
one of the classes in the user-defined set.
Simple classification algorithms are the box and the minimum distance classifiers.
During box classification, a box is created around the training feature vectors of
each class. A box is rectangle in a two-dimensional feature space, a block in the
three-dimensional case, or a hyper-block if there are more than three features. The
position and size of the box of a class can be exactly around the feature vectors
of the training samples (min-max method), or according to the mean vector and
the standard deviations of these feature vectors. Each image pixel is then classified
according to the box that contains its feature vector. In parts of the feature space
where boxes overlap, it is usual to give priority to the smallest box. Feature vectors
in the image that fall outside all boxes will be classified unknown.
A minimum distance-to-mean classifier first calculates for each class the mean
vector of the training feature vectors. The feature space is partitioned by giving to
each feature vector the class label of the nearest mean vector, according to Euclidian
metric. Usually it is possible to specify a maximum distance threshold: if the nearest
mean is still further away than that threshold, is is assumed that none of the classes
is similar enough and the result will be unknown.
7.4.2 Maximum Likelihood Classification
Whereas the above-mentioned classifiers use rather heuristical decision rules, maximum likelihood classification has a statistical foundation.
Maximum likelihood aims at assigning a "most likely" class label Gi , from a set
of N classes G 1, ... , G N, to any feature vector x in an image.
The most likely class label Gi for a given feature vector x is the one with the
highest posterior probability P(Gilx). Each P(Gilx), i E [l..N], is calculated, and
the class Gi with the highest value is selected. The calculation of P( Gilx) is usually
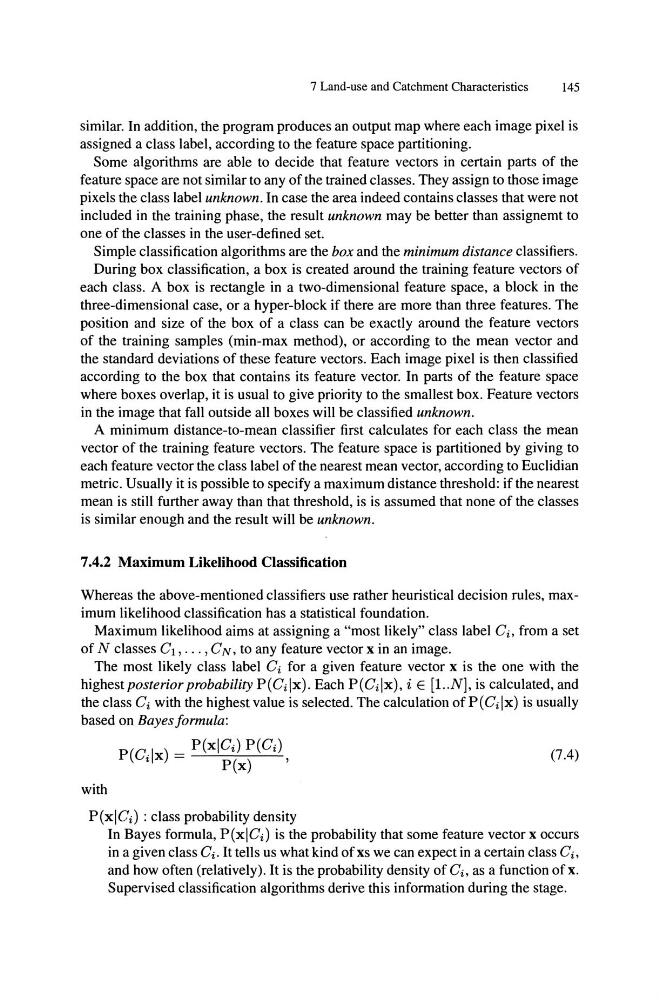
based on Bayesformula:
(7.4)
with
P(xIGi) : class probability density
In Bayes formula, P(xIGi) is the probability that some feature vector x occurs
in a given class Gi. It tells us what kind of xs we can expect in a certain class Gi,
and how often (relatively). It is the probability density of Gi , as a function ofx.
Supervised classification algorithms derive this information during the stage.