

362
11. Efficiency and Accuracy Improvement
ary conditions, which simulates the pressure-correction equation in CFD applications, are shown in Fig. 11.13. With one pre-conditioner sweep per CG
iteration, the number of iterations required for convergence increases with
the number of processors. However, with two or more pre-conditioner sweeps
per CG iteration, the number of iterations remains nearly constant. However,
in different applications one may obtain different behaviour.
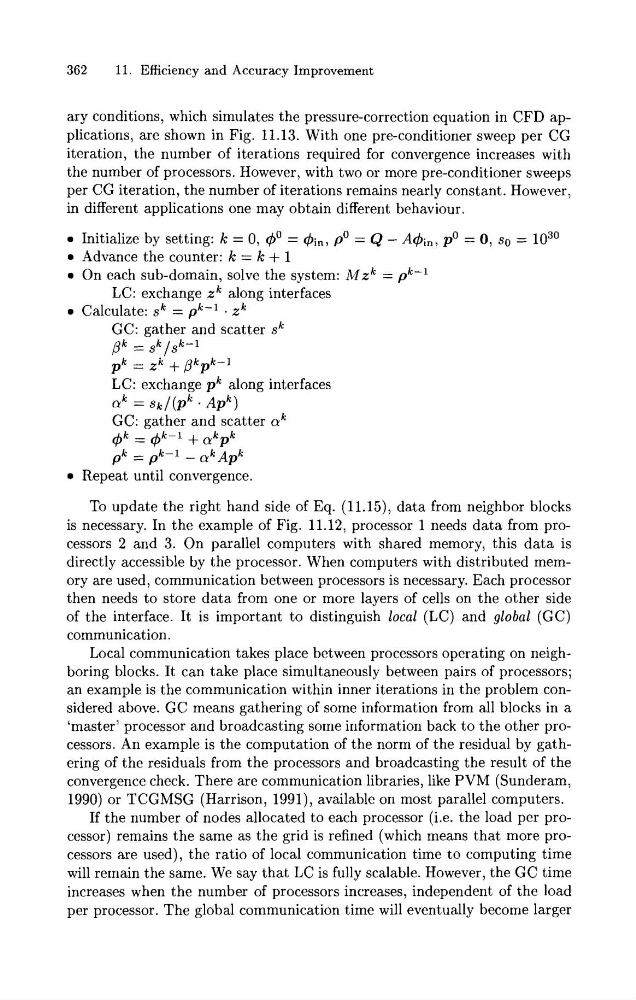
0 Initialize by setting: k = 0, 4' = + i n , p0 = Q - A@;,, p0 = 0, so = lo3'
0 Advance the counter: k = k + 1
0 On each sub-domain, solve the system: ~z~ = pk-l
LC: exchange z k along interfaces
0 Calculate: sk = pk--' . z k
GC: gather and scatter sk
p = sk/&l
p' E = z k + p p k - 1
LC: exchange pk along interfaces
ak = s k / ( p k ' A p k )
GC: gather and scatter ak
q5k = q s - 1 + a k p k
pk = p k - l - ak Apk
0 Repeat until convergence.
To update the right hand side of Eq. (11.15), data from neighbor blocks
is necessary. In the example of Fig. 11.12, processor 1 needs data from processors 2 and 3. On parallel computers with shared memory, this data is
directly accessible by the processor. When computers with distributed memory are used, communication between processors is necessary. Each processor
then needs to store data from one or more layers of cells on the other side
of the interface. It is important to distinguish local (LC) and global (GC)
communication.
Local communication takes place between processors operating on neighboring blocks. It can take place simultaneously between pairs of processors;
an example is the communication within inner iterations in the problem considered above. GC means gathering of some information from all blocks in a
'master' processor and broadcasting some information back t o the other processors. An example is the computation of the norm of the residual by gathering of the residuals from the processors and broadcasting the result of the
convergence check. There are communication libraries, like PVM (Sunderam,
1990) or TCGMSG (Harrison, 1991), available on most parallel computers.
If the number of nodes allocated to each processor (i.e. the load per processor) remains the same as the grid is refined (which means that more processors are used), the ratio of local communication time to computing time
will remain the same. We say that LC is fully scalable. However, the GC time
increases when the number of processors increases, independent of the load
per processor. The global communication time will eventually become larger