

4.2 Data Preprocessing
In order to transform raw data into an understandable format, we aim to apply data
preprocessing techniques to build machine learning classifier. In fact, the data should
be cleaned and preprocessed to eliminate characteristics of less important data and
improve accuracy. For this purpose, we used machine learning techniques such as
lowercasing which defines a common approach to reduce all the text to lower case for
simplicity, Tokenization which assumes splitting text into tokens, Punctuation
Removal which is a form of pre-processing to filter out useless data and Stop words
Removal.
4.3 Data Representation
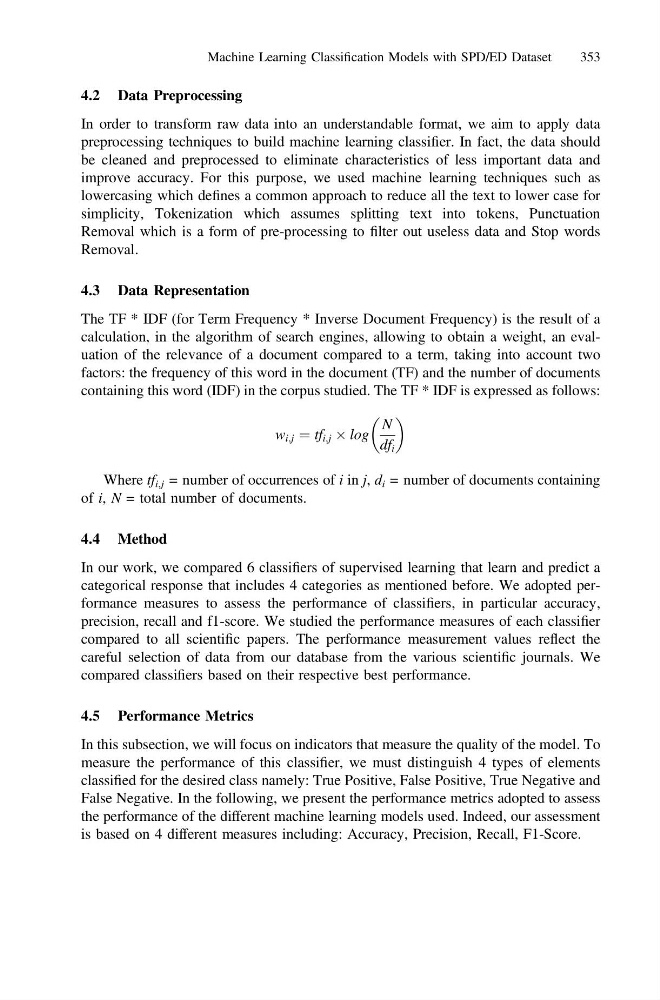
The TF * IDF (for Term Frequency * Inverse Document Frequency) is the result of a
calculation, in the algorithm of search engines, allowing to obtain a weight, an evaluation of the relevance of a document compared to a term, taking into account two
factors: the frequency of this word in the document (TF) and the number of documents
containing this word (IDF) in the corpus studied. The TF * IDF is expressed as follows:
w i;j ¼ tf i;j  log
N
df i
Where tf i,j = number of occurrences of i in j, d i = number of documents containing
of i, N = total number of documents.
4.4 Method
In our work, we compared 6 classifiers of supervised learning that learn and predict a
categorical response that includes 4 categories as mentioned before. We adopted performance measures to assess the performance of classifiers, in particular accuracy,
precision, recall and f1-score. We studied the performance measures of each classifier
compared to all scientific papers. The performance measurement values reflect the
careful selection of data from our database from the various scientific journals. We
compared classifiers based on their respective best performance.
4.5 Performance Metrics
In this subsection, we will focus on indicators that measure the quality of the model. To
measure the performance of this classifier, we must distinguish 4 types of elements
classified for the desired class namely: True Positive, False Positive, True Negative and
False Negative. In the following, we present the performance metrics adopted to assess
the performance of the different machine learning models used. Indeed, our assessment
is based on 4 different measures including: Accuracy, Precision, Recall, F1-Score.
Machine Learning Classification Models with SPD/ED Dataset
353