

202
12 Cryptocurrencies
of the input signal H [x] = H b (α) and the entropy that is added by the random bit
changes in the transmission channel H b (ε).
We can now replace p xy (x i , y j ) = p yx (y j |x i ) p x (x i ), known from (12.9), in the
logarithm and write the product in the logarithm as a sum of two terms. We find the
so-called chain rule
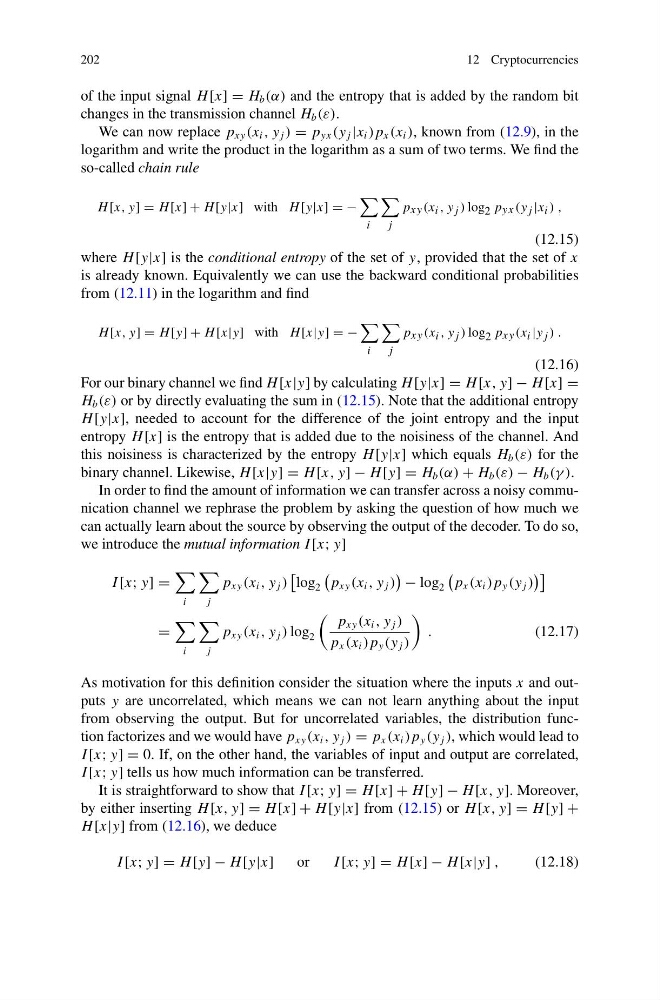
H [x, y] = H [x] + H [y|x] with H [y|x] = −
i
j
p xy (x i , y j ) log 2 p yx (y j |x i ) ,
(12.15)
where H [y|x] is the conditional entropy of the set of y, provided that the set of x
is already known. Equivalently we can use the backward conditional probabilities
from (12.11) in the logarithm and find
H [x, y] = H [y] + H [x|y] with H [x|y] = −
i
j
p xy (x i , y j ) log 2 p xy (x i |y j ) .
(12.16)
For our binary channel we find H [x|y] by calculating H [y|x] = H [x, y] − H [x] =
H b (ε) or by directly evaluating the sum in (12.15). Note that the additional entropy
H [y|x], needed to account for the difference of the joint entropy and the input
entropy H [x] is the entropy that is added due to the noisiness of the channel. And
this noisiness is characterized by the entropy H [y|x] which equals H b (ε) for the
binary channel. Likewise, H [x|y] = H [x, y] − H [y] = H b (α) + H b (ε) − H b (γ ).
In order to find the amount of information we can transfer across a noisy communication channel we rephrase the problem by asking the question of how much we
can actually learn about the source by observing the output of the decoder. To do so,
we introduce the mutual information I [x; y]
I [x; y] =
i
j
p xy (x i , y j )
log 2
p xy (x i , y j )
− log 2
p x (x i ) p y (y j )
=
i
j
p xy (x i , y j ) log 2
p xy (x i , y j )
p x (x i ) p y (y j )
.
(12.17)
As motivation for this definition consider the situation where the inputs x and outputs y are uncorrelated, which means we can not learn anything about the input
from observing the output. But for uncorrelated variables, the distribution function factorizes and we would have p xy (x i , y j ) = p x (x i ) p y (y j ), which would lead to
I [x; y] = 0. If, on the other hand, the variables of input and output are correlated,
I [x; y] tells us how much information can be transferred.
It is straightforward to show that I [x; y] = H [x] + H [y] − H [x, y]. Moreover,
by either inserting H [x, y] = H [x] + H [y|x] from (12.15) or H [x, y] = H [y] +
H [x|y] from (12.16), we deduce
I [x; y] = H [y] − H [y|x]
or
I [x; y] = H [x] − H [x|y] ,
(12.18)