

70
4 Advanced Neural Networks
|g i =
⎛
⎜
⎜
⎜
⎜
⎜
⎝
0
1
0
. . .
0
⎞
⎟
⎟
⎟
⎟
⎟
⎠
.
(4.39)
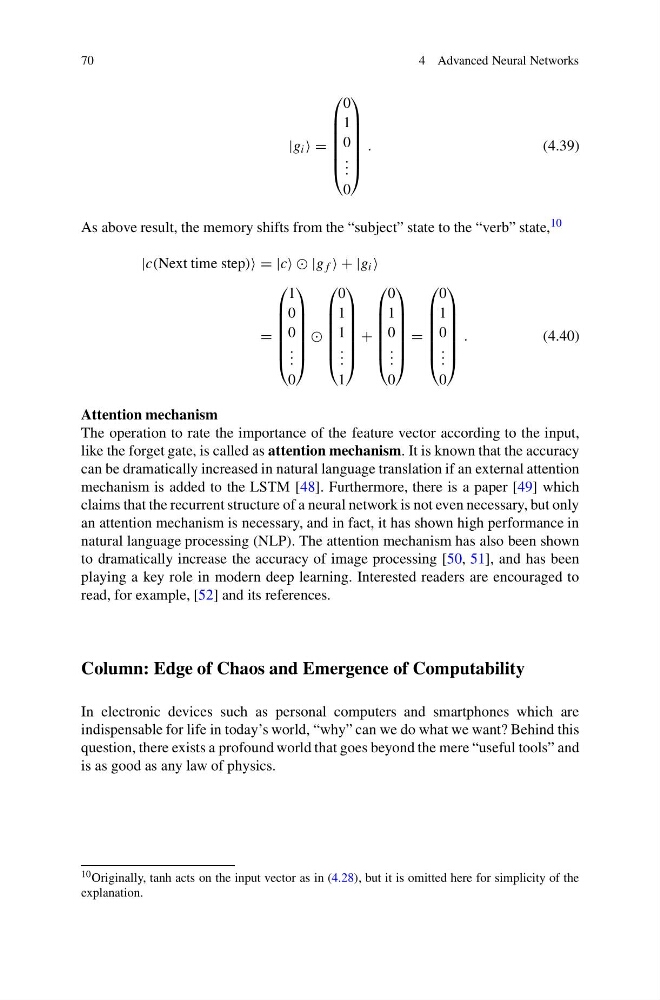
As above result, the memory shifts from the “subject” state to the “verb” state, 10
|c(Next time step) = |c |g f + |g i
=
⎛
⎜
⎜
⎜
⎜
⎜
⎝
1
0
0
. . .
0
⎞
⎟
⎟
⎟
⎟
⎟
⎠
⎛
⎜
⎜
⎜
⎜
⎜
⎝
0
1
1
. . .
1
⎞
⎟
⎟
⎟
⎟
⎟
⎠
+
⎛
⎜
⎜
⎜
⎜
⎜
⎝
0
1
0
. . .
0
⎞
⎟
⎟
⎟
⎟
⎟
⎠
=
⎛
⎜
⎜
⎜
⎜
⎜
⎝
0
1
0
. . .
0
⎞
⎟
⎟
⎟
⎟
⎟
⎠
.
(4.40)
Attention mechanism
The operation to rate the importance of the feature vector according to the input,
like the forget gate, is called as attention mechanism. It is known that the accuracy
can be dramatically increased in natural language translation if an external attention
mechanism is added to the LSTM [48]. Furthermore, there is a paper [49] which
claims that the recurrent structure of a neural network is not even necessary, but only
an attention mechanism is necessary, and in fact, it has shown high performance in
natural language processing (NLP). The attention mechanism has also been shown
to dramatically increase the accuracy of image processing [50, 51], and has been
playing a key role in modern deep learning. Interested readers are encouraged to
read, for example, [52] and its references.
Column: Edge of Chaos and Emergence of Computability
In electronic devices such as personal computers and smartphones which are
indispensable for life in today’s world, “why” can we do what we want? Behind this
question, there exists a profound world that goes beyond the mere “useful tools” and
is as good as any law of physics.
10 Originally, tanh acts on the input vector as in (4.28), but it is omitted here for simplicity of the
explanation.